Why academics should self publish textbooks

I have self-published my two textbooks, Data Science for Crime Analysis with Python, and Large Language Models for Mortals: A Practical Guide for Analysts with Python. I have written about my set up previously, long story short use Quarto to compile the books to epub and a nice PDF, and then use LuLu for print on demand.

I figured a blog post on why I think all academics should take this route when publishing textbooks is in order though.

Reason #1 – you can set the cost.

Most textbooks are ridiculously overpriced. My two books I sell at print prices of $50 and $60. These are textbooks that are over 200 pages in a larger letter paper size. If they were the smaller size, they would be 400+ pages, and priced for print well over $100 (and possibly over $200). The actual print costs for each of my books are around $20 and $30 (and then $6 to $10 for shipping). And of course selling the epub is basically zero cost.

Many professors write their own textbooks because they teach a course that does not have a standard text. (Most are not doing it to make a buck.) You can make a buck if you want, and still sell the books for less than half of what an academic publisher would charge for the book.

So without a coupon, I make about $30 when I sell a print version of either of my books. (If professors adopt one of my books for the course, I give coupons so I only make $10 margin per book, either print or epub.)

To be clear, I do not suggest writing your own textbook to fleece your students. But if you do write a good textbook for a course, why not make it more broadly available to everyone?

Margins for professors selling a book through a traditional publisher are typically around $1 per sale. Again I sell my books for less than half of what an academic publisher would sell them for, and make closer to $30 per sale on average.

Reason #2 – you have full control over the content and layout.

My books are letter-sized (8.5 by 11 inches), not the more typical 6 by 9 inches. This is based on personal preference, one I think many will share when writing technical textbooks. The code snippets in the book look much nicer with the larger pages – I can have larger code-snippet sections. It also allows me to have larger images, without odd artifacts with the ragged bottom for the print version.

I have posted my Quarto and LaTeX notes on my book set up. If you are not familiar with Quarto, you write your book in plain text Markdown, and then have a tool compile the book to the different end formats. For those not familiar, Markdown looks like:

# This is a title

A section describing something ...

![An image caption](Figure1.png)

So you write in a plain text, and then have a tool turn the plain text into different formats. For print, you will make a PDF version to send to the service that prints the book. You can also make an epub (or just share the PDF) as well, or make an HTML website. (Jacob Kaplan’s Crime by the Numbers: A Criminologist’s Guide to R is a good example website that also has a book, which costs over $100 for the print version.)

One of the points I have never seen another editor make – epubs should be formatted differently than print. I use different fonts for the different versions of my books. This is easily possible with just changing the meta-data in Quarto (and would work the same if just using Pandoc to directly convert as well, this advice is not specific for those writing coding books).

Reason #3 – you can update the content as much as you please.

If you want a textbook, printed through a traditional academic publisher, it would take around a year to go through the motions of updating the draft, getting editor feedback, and going into print. You can do updates as fast as you want when self-publishing. You spot an error, you can have an errata and simultaneously fix it for all future versions as fast as you can do the edits.

Many academics do not care about this very much, but when writing textbooks that include code, I do. Code can go bad, particularly when writing about contemporary topics like large language model APIs.

Pre-empting some reasons to not self-publish

Now some will read the above statements and (reasonably) think those benefits can be bad. It can be bad that you have full control over the layout, most people will not care. It could be bad you have the obligation to update the text yourself (without an intermediary copy-editor).

I have published two other textbooks through traditional academic publishers, and to be honest these things are not something you should value all that much. The amount of copy-editing you get from a traditional publisher is pretty minimal. If you read my description of markdown above and think, I don’t want to have to figure that out, just get a $20 subscription to OpenAI or Claude, give it the link to this blog post, and ask it to set your computer up for you. Even if you do not want AI to help you write (you should definitely use it as a copy-editor for slight grammar and spelling errors), this is worth your time.

There are two aspects that self-publishing are clearly worse though than going through a traditional academic publisher – distributing your book and potential prestige. For the prestige point, I am talking about academic textbooks (like those published by Springer, Wiley, Pearson, university presses, etc.). Most people do not consider them prestigious, but I have no doubt some fool Dean bean-counts those as publications for tenure and will discount self-published books. They should not, but I am sure some do. For the small number that have a fool for a dean, I am sorry about your current lot in life.

For distributing your textbook, it is easier to get a textbook in a university library through a traditional academic publisher. I go through the whole process of getting an ISBN, copyright, and submitting my books to the Library of Congress. So libraries can (and have when professors request it) made purchases of my textbook. I imagine if you publish a textbook with Wiley though they have standard ways to get books into libraries, go to conferences and have a stand, etc.

Ask a friend who has published a textbook the benefit of this next time you meet. They will tell you something like “I don’t know what you are talking about, I only sold 12 copies last year”. If you can get a For Dummies book, this is not the same as an academic publisher. The University of Punxsutawney press is not hustling to sell your book in Barnes & Noble.

So do your students and yourself a favor, self publish that textbook.

VerusCite is now $1, Crime De-Coder Store updates, CCJ Homicide Report, and some more AI papers

For several minor updates across my different projects. One, I have updated my Crime De-Coder store where I sell my books and software. Before, it was a WooCommerce site, which worked ok (pure GUI integration). But it was time for me to upgrade and have it directly integrated into my site.

It was a WooCommerce site before, which worked ok (pure GUI integration). But it was time for me to upgrade and have it directly integrated into my site. So now it is using the direct print API from LuLu for the books, and everything else is custom PHP code. Using Opus 5.5, this was just a day of tinkering. For several coupon codes:

  • LLMDEVS, $25 off LLM for Mortals epub
  • TWOFOR1, $30 off if you purchase any two books
  • SIXPRINT, $20 off LLM Mortals paperback
  • NEWSTORE, $20 off any of my Data Science for Crime Analysis book (paperback or epub, in any language)

VerusCite is now only $1 to review a paper. Between Luna 6.0 pricing and Perplexity fast web search being cheaper, it has brought costs down far enough for me to offer it at $1 per check.

Also VerusCite has its first retraction, a paper in Policing: An International Journal. Sign up and let your editor friends know about the tool!

The Council on Criminal Justice has released their report on the expert opinions on the homicide decline. I was invited, and thought it was well run. There was not much agreement on what caused the decline (which is difficult if not impossible in noisy crime data), but there was agreement on factors that likely did not contribute to the decline. Take this example of why I think increased firearm carrying is not a likely contributor to the recent homicide decline.

If you are interested in this report, I also made two different web apps to peruse different national level crime trends (based on Jeff Asher’s real-time-crime-index sample of 500+ cities across the US). The Crime Decomposition Explorer, where you can see a single city and compare their trends to the rest of the US. Or the Synth app, where you can conduct a synthetic control estimate for a specific city, timepoint, and crime type of your choosing.

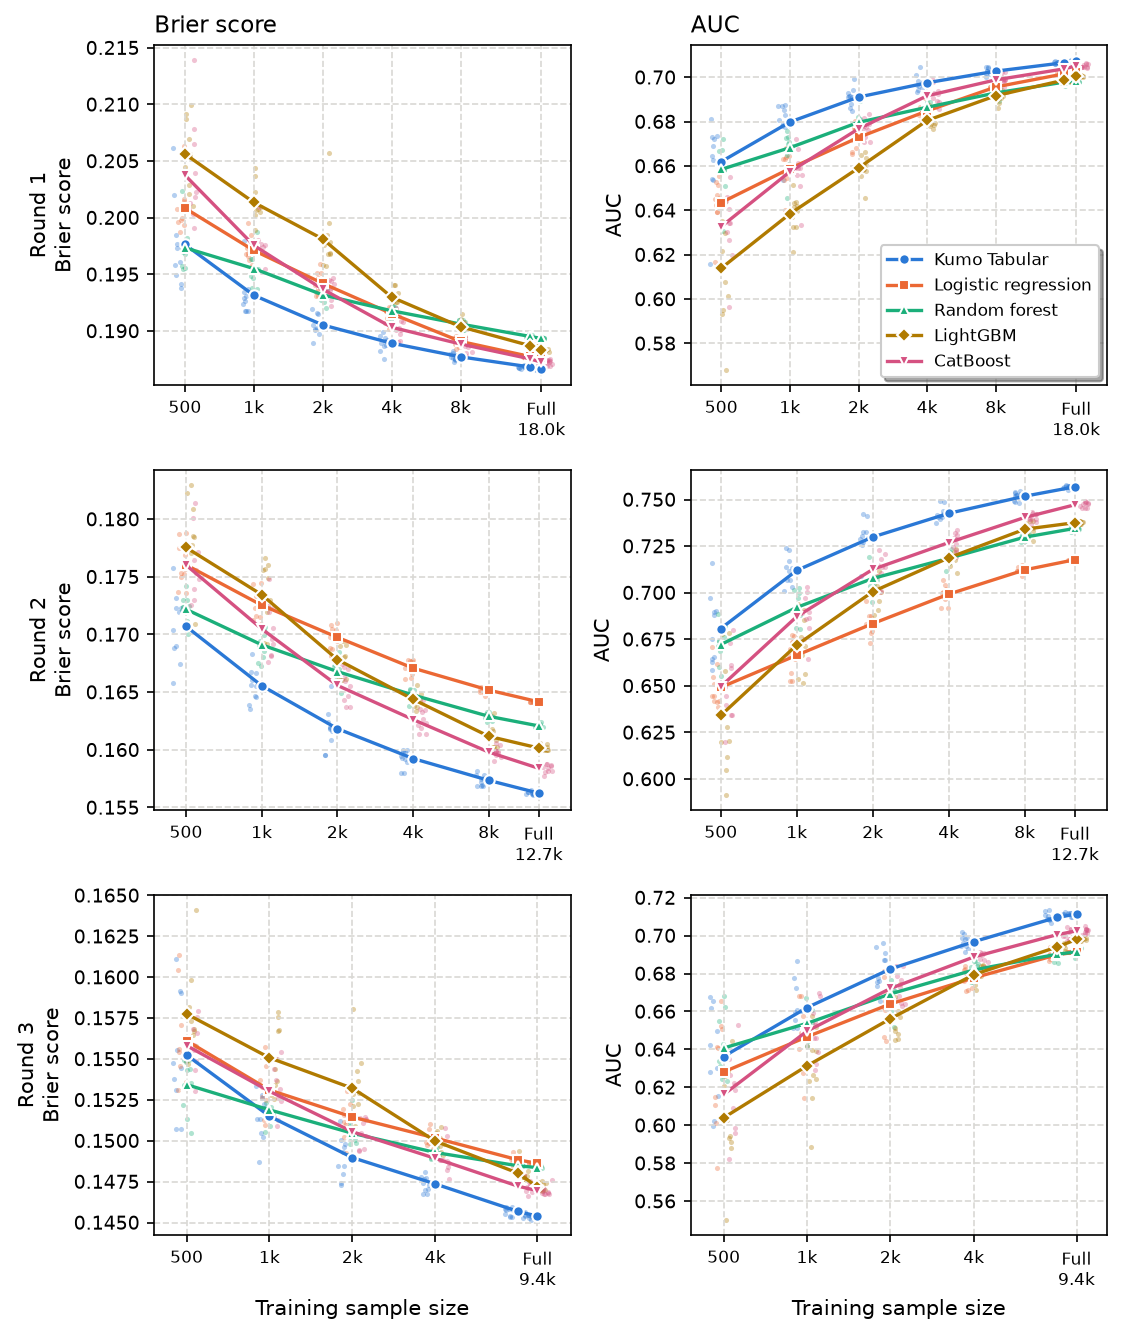
In continuing with my tests in having AI write whole papers, I have two additional ones. Using NVIDIA’s newest tabular foundation model Kumo, I show it would have done quite well in the NIJ recidivism competition without feature engineering. It basically would have placed on the large team leaderboard for the majority of the competition sub-categories.

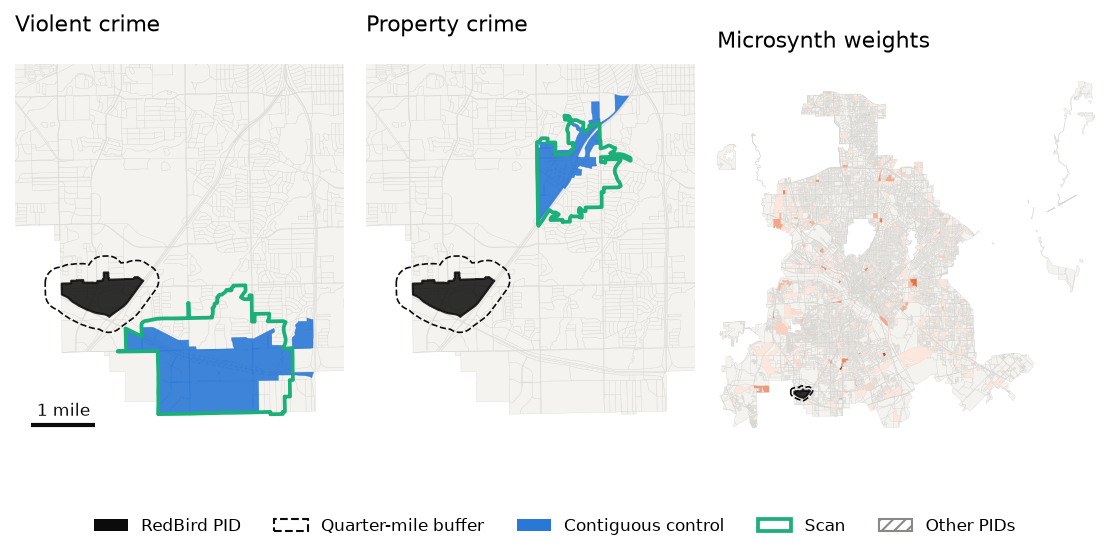
Another AI paper is developing a spatial scan technique to choose a control area for a place based crime intervention. This is a follow up to the WDD paper I wrote with Jerry – this is a way for an analyst to have a data driven approach to choose a control area that follows similar crime trends.

I do not like microsynth (it clearly is overfitting to the data), and in the pretty tame simulations I show the chosen control area is less biased.

I did actually have GrokBot upload one of my AI papers to crimrxiv – Fair and efficient spatial siting of public surveillance cameras. I may upload more of them at a later date, I am not 100% sure. (I am unlikely to spend the time to get them peer reviewed though; they will get more views on my blog and via crimrxiv than they would in a peer-reviewed publication.)

If you are interested in training, though, for your graduates or program, get in touch. I have been sending out emails to programs to encourage departments to pay for Python training or training on using LLMs. The current AI tools can (and should) definitely be used effectively and safely for social science research. Academics are just sticking their heads in the sand if they think AI cannot or should not be used to help with research and writing.

Join CrimConsortium, ASEBP submissions open, VerusCite privacy, NACA Course

I have minor updates for several activities.

First, the American Society of Evidence-Based Policing is accepting submissions for its conference in spring 2027 at UPenn:

If you are a vendor interested in promoting some of your work at the conference, also feel free to get in touch. I serve on the committee that works with vendors and the committee that reviews proposals.

Second, I have updated several of the pages for Crim Consortium (roughly the nonprofit behind CrimRXiv).

For individuals, you should consider becoming a member to support the work Scott (and to a lesser extent myself) is doing on this. (We do not make money to be clear, just keeping the lights on.)

If you are a program head for a department (or involved in some other organization), you should consider becoming an institutional member. You get your own prioritized page (which is worth it just for the SEO for your group).

CrimRXiv has over a million pageviews per month at the moment. It is easily the best preprint server to post your work to for anything related to criminology at all. It is also the only preprint server that lets you upload your work in HTML format (you can upload a Markdown or LaTeX file as well and it turns the paper into HTML). So you can have embedded interactive graphics if you want, for example.

Third, VerusCite has a blog with the most recent post about How VerusCite Handles Privacy. For individuals running journals, I only submit the references to the LLMs, unlike other editors. Those LLMs are zero-data-retention, and I also do not see what you upload.

Journals should really be investing in my tool. Most journals would only take a few hundred per year at $2 per paper.

This is a major problem across science as a whole at the moment. The Hall of Hallucinations is up to 27 papers as of this writing, and I tend to add at least one a day.

Fourth, I have contributed a course to the new National Association of Crime Analysts called Basics of Python Programming for Crime Analysts.

This asynchronous course consists of bite-sized labs to go with my book, Data Science for Crime Analysis with Python. If you would like in-person training, get in touch, but this is much more economical for those interested in pursuing training on their own.

AI writing is better than no writing

AI disclosure – this post was entirely written by myself.

I know AI writing is still pretty cringey – so I get that people are quite opposed to it. For people like me though (academics promoting their work, more technical oriented) I would like to proffer a slight defense of (even cringey) AI writing. Having an LLM tool help you write a blog post is better than not writing at all.

I have come to the personal opinion I just want you to disclose when you use AI. I am starting to get peer review requests for academic papers that are clearly LLM written, and they are not obviously worse than the typical (mostly horrid) way academics write papers (they may actually be better to be honest). Blog and social media posts I think are strictly worse to my personal tastes when using LLM writing (across many dimensions, for now anyway). But it is better to write something than nothing if you have something worth saying.

Where this matters for technical folks (and academics) is that your default SEO is awful. Most academic papers are behind paywalls. LLM research tools are not picking up peer reviewed papers. So if you have something worth saying, having LLMs write out a blog post for you is worth it relative to having no writing at all.

For examples of LLM writing I have on this site:

And then my book, Large Language Models for Mortals: A Practical Guide for Analysts with Python, is around 50% AI generated.

None of these examples I would have finished without the help of AI; either entirely writing for the example blog posts, or writing the first draft in the case of the LLM book. (The LLM book is good by the way, you would not be able to tell I generated that first draft at all with Claude.)

My suggestion is to not let AI entirely take the wheel, but to create a detailed outline and have the LLM review your prior writing. Those two things improve posts by a wide margin (in addition to making sure AI is not too verbose – keep those blog posts simple!). And then you still need to take the time to review your own writing (for references you need to check those for hallucinations).

To be clear again, AI writing is better than nothing if you have something actually useful to say to the world. The bigger issue with AI writing are slop merchants just wasting space. That happened before with LLM tools, it is just much easier and more prevalent now. Just own it when you use AI to help you write.

Pangram is good

Many of the initial wave of “AI writing detectors” were quite bad. The biggest issue you need to be concerned about with an AI writing detector is false positives. If you are a professor and want to check students’ writing, it is very bad to falsely accuse a student.

The Pangram product, though, is quite good, and I suggest folks check it out.

The other main competitor on the market, GPTZero, is clearly lower quality (such as saying the Constitution is AI generated).

GPTZero in their documentation says they are the most accurate AI detector. One of the reasons you don’t really care about accuracy is that you cannot know the underlying rate of AI writing in any corpus except in the scenario where it is artificially generated. And that is the only scenario in which you can know the accuracy for sure. What you care about is specifically the false positive rate and the false negative rate.

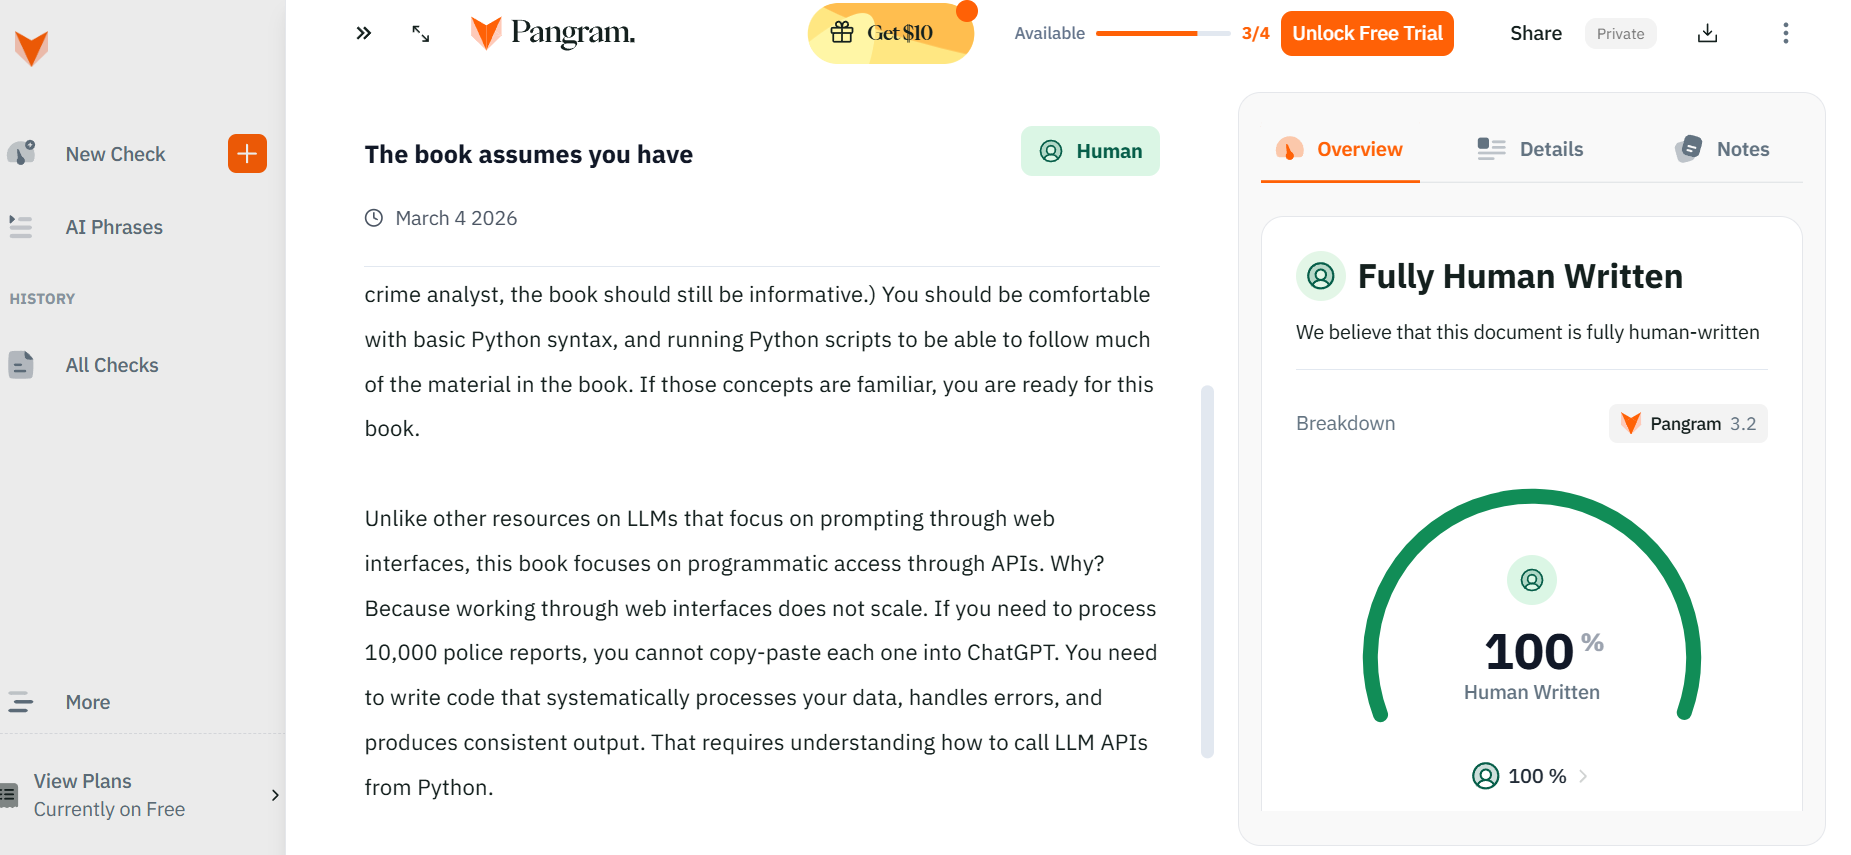
Unlike GPTZero, Pangram appears to have very low false positive rates. A simple way to estimate the false positive rate is to just submit writing prior to 2022 to the tool and see how many it flags as AI. ChatGPT came out in late 2022, the tools to generate writing before that were just not even close for people to use in any serious way. So any writing flagged in the older corpus as AI is a false positive.

Here is an example examining legal briefs.

It is an independent assessment. We cannot really know the capture rate (were there more than 66 briefs generated via LLMs in that sample). We can know the false positive rate though. And it is 1/800 in this sample with Pangram.

Pangram says it has a 1 in 10,000 false positive rate across a wide array of writing samples. They even report in their own internal tests that GPTZero has a 2% false positive rate (I am pretty sure GPTZero’s false positive rate is much higher than 2%, hence the Constitution error.)

Many other checks for false negative rates involve people having various models generate writing and then classifying it. It is hard to know if those are very good benchmarks for estimating the false negative rate. But we can easily estimate the false positive rate, and in that respect Pangram is clearly better than other AI writing detectors on the market.

Should we care if writing is AI?

I have used AI tools to help me write. I promise to be forthcoming if I use AI to help me write any substantive sections of writing (in blog posts, books, social media posts, etc.) Currently I am almost always using the LLMs to copy-edit, which is often simply a prompt “check for spelling and grammar issues”.

I do not use it all the time for writing. This post was all written by hand (and then just copy-edited with Gemini CLI).

It is really not that hard to bring your own voice and use AI to aid your writing. Have the LLM read your prior work, then give it a detailed outline, and then iterate. See my transcript on a prior post for an example.

I’d note I have used Pangram to see if my LLM writing is too obviously AI, and it is not. To me, when the writing is clearly AI, this often signals a clear lack of care and effort in the writing. AI writing can be valuable, but it is quite frequently low value slop.

So you get people larping as tech experts.

You can trivially have Claude or whatever software write a Skill file, and then have an LLM write how it is super awesome. This does not make it so.

And you have salespeople write posts that literally make no sense.

This, to be clear, is obviously AI slop.

So these individuals could actually generate useful content if they spent any more than a trivial amount of time. But they don’t, and it shows.

LinkedIn Premium Does Not Boost your Posts

One of my connections mentioned in a post on LinkedIn that since he turned off Premium, his posts have been getting less engagement. Since LinkedIn offers a month for free, and I have been trying to promote my recent book, I figured I would try my free month trial and see how many more views I could get. (Here I am not worried about Premium for applying to new jobs, it is possible it is totally worth it for that, I was not applying to jobs in this test so I do not know.)

Long story short, LinkedIn Premium does not appear to promote my material at all above the baseline.

Post Views

In a sample of 30 posts the month before I turned on Premium (turned on 3/24 in the evening, turned off 4/22 in the morning), my posts had an average of 3600 views (with a standard deviation of 7000, median 1400). Post-Premium, I had 23 posts, and the views were on average 2200 (SD 2900, median 900). Here is the full table of posts and links (Premium=1 means it was posted when my Premium subscription was turned on):

| Premium | Views | URL |
| ----:|----- :|:----- |
| 0    | 3659  | https://www.linkedin.com/posts/andrew-wheeler-46134849_llms-have-transformed-the-data-science-industry-activity-7426975341572984832-HGTA |
| 0    | 2526  | https://www.linkedin.com/posts/andrew-wheeler-46134849_no-guarantees-but-i-am-going-to-try-to-start-activity-7428418993553846272-vdjA    |
| 0    | 2290  | https://www.linkedin.com/posts/andrew-wheeler-46134849_much-of-the-hype-around-claude-code-is-having-activity-7428781380391567360-zkXr   |
| 0    | 545   | https://www.linkedin.com/posts/andrew-wheeler-46134849_one-of-the-benefits-of-my-epub-version-of-activity-7429143771109302272-_V6T       |
| 0    | 1454  | https://www.linkedin.com/posts/andrew-wheeler-46134849_claude-code-has-the-ability-to-create-hooks-activity-7429506167527088128-01Um     |
| 0    | 1326  | https://www.linkedin.com/posts/andrew-wheeler-46134849_one-of-the-prompting-flows-i-find-convenient-activity-7429868558794436609-SDgG    |
| 0    | 1278  | https://www.linkedin.com/posts/andrew-wheeler-46134849_one-of-the-main-focuses-in-the-book-is-not-activity-7430230940444057600-pqK-      |
| 0    | 5988  | https://www.linkedin.com/posts/andrew-wheeler-46134849_while-skills-in-claude-code-are-all-the-rage-activity-7430955707358818304-iqjb    |
| 0    | 1726  | https://www.linkedin.com/posts/andrew-wheeler-46134849_one-of-the-mistakes-i-see-with-agent-based-activity-7431318102212100096-rI_W      |
| 0    | 1172  | https://www.linkedin.com/posts/andrew-wheeler-46134849_from-my-experience-as-an-educator-when-presenting-activity-7431680485585580032-8h7B    |
| 0    | 1360  | https://www.linkedin.com/posts/andrew-wheeler-46134849_although-the-llm-tools-are-currently-focused-activity-7432042882770944000-AfAG    |
| 0    | 5304  | https://www.linkedin.com/posts/andrew-wheeler-46134849_when-i-was-a-professor-at-ut-dallas-i-sat-activity-7432405268874817536-qrAI       |
| 0    | 30732 | https://www.linkedin.com/posts/andrew-wheeler-46134849_i-know-a-few-stats-folks-in-my-network-that-activity-7432767666781679617-HXnk |
| 0    | 1003  | https://www.linkedin.com/posts/andrew-wheeler-46134849_claude-code-does-not-have-an-image-model-activity-7433492422111776768-2dqY        |
| 0    | 884   | https://www.linkedin.com/posts/andrew-wheeler-46134849_while-i-have-a-section-in-the-book-devoted-activity-7433854815862013952-FIl-      |
| 0    | 888   | https://www.linkedin.com/posts/andrew-wheeler-46134849_in-the-book-i-have-a-dedicated-chapter-on-activity-7434217215450681344-hk3E       |
| 0    | 1868  | https://www.linkedin.com/posts/andrew-wheeler-46134849_the-llm-book-is-compiled-using-quarto-so-activity-7434579595095580673-RHdx        |
| 0    | 807   | https://www.linkedin.com/posts/andrew-wheeler-46134849_llms-for-mortals-how-to-view-the-epub-activity-7434945455073169409-bNDu           |
| 0    | 1243  | https://www.linkedin.com/posts/andrew-wheeler-46134849_section-on-using-gliner-for-ner-activity-7435304382931513344-NPPC                 |
| 0    | 1745  | https://www.linkedin.com/posts/andrew-wheeler-46134849_my-first-book-data-science-for-crime-analysis-activity-7436029137695416320-aRmr   |
| 0    | 914   | https://www.linkedin.com/posts/andrew-wheeler-46134849_so-the-new-book-large-language-models-for-activity-7436376426100199424-1g8E       |
| 0    | 1593  | https://www.linkedin.com/posts/andrew-wheeler-46134849_agentic-coding-apps-like-claude-code-and-activity-7436738847054512128-qiXz        |
| 0    | 3415  | https://www.linkedin.com/posts/andrew-wheeler-46134849_many-people-are-turned-off-by-ai-writing-activity-7437101213717909504-QjOo        |
| 0    | 928   | https://www.linkedin.com/posts/andrew-wheeler-46134849_pretty-much-every-day-there-is-a-new-prompt-activity-7437463609401794560-50H-     |
| 0    | 2185  | https://www.linkedin.com/posts/andrew-wheeler-46134849_much-of-the-hype-around-skills-is-imo-people-activity-7437826000958337024-t6i3    |
| 0    | 800   | https://www.linkedin.com/posts/andrew-wheeler-46134849_one-of-the-benefits-of-my-llm-for-mortals-activity-7438550758763098112-hQUw |
| 0    | 870   | https://www.linkedin.com/posts/andrew-wheeler-46134849_large-language-models-for-mortals-preview-activity-7438913140639207424-tAli       |
| 0    | 1948  | https://www.linkedin.com/posts/andrew-wheeler-46134849_new-blog-post-using-claude-code-to-help-activity-7441087469388861440-TCKq         |
| 0    | 1160  | https://www.linkedin.com/posts/andrew-wheeler-46134849_given-all-the-rage-with-generative-ai-and-activity-7441449857480933377-uPFw       |
| 0    | 27842 | https://www.linkedin.com/posts/andrew-wheeler-46134849_stop-teaching-r-teach-python-when-i-was-activity-7441812266938826753-DywF         |
| 1    | 526   | https://www.linkedin.com/posts/andrew-wheeler-46134849_forecasting-the-future-is-difficult-especially-activity-7442537064803368960-qsVO  |
| 1    | 13096 | https://www.linkedin.com/posts/andrew-wheeler-46134849_when-using-llms-to-do-structured-data-extraction-activity-7442899426471407617-CpZz |
| 1    | 2394  | https://www.linkedin.com/posts/andrew-wheeler-46134849_ive-spoken-with-many-people-who-are-concerned-activity-7443039100477145090-v_3i   |
| 1    | 646   | https://www.linkedin.com/posts/andrew-wheeler-46134849_the-main-audience-my-book-large-language-activity-7443261810511757312-R2Jc        |
| 1    | 3030  | https://www.linkedin.com/posts/andrew-wheeler-46134849_for-the-folks-that-were-not-happy-with-my-activity-7443401497444409344-q38H       |
| 1    | 437   | https://www.linkedin.com/posts/andrew-wheeler-46134849_one-of-the-current-capabilities-of-googles-activity-7443624184120754176-YHbw      |
| 1    | 5275  | https://www.linkedin.com/posts/andrew-wheeler-46134849_one-error-i-am-seeing-devs-continually-make-activity-7443986571650973696-TZ-K     |
| 1    | 3815  | https://www.linkedin.com/posts/andrew-wheeler-46134849_one-of-the-biggest-issues-with-using-generative-activity-7444348969100664832-pX0v |
| 1    | 738   | https://www.linkedin.com/posts/andrew-wheeler-46134849_reports-of-rags-demise-are-overstated-activity-7444711358421491712-6BJu           |
| 1    | 425   | https://www.linkedin.com/posts/andrew-wheeler-46134849_the-recent-litellm-distribution-attack-highlights-activity-7445073747968999424-NEmn    |
| 1    | 3752  | https://www.linkedin.com/posts/andrew-wheeler-46134849_one-of-the-responses-to-me-writing-the-book-activity-7445436130080186369-7Fvx     |
| 1    | 1670  | https://www.linkedin.com/posts/andrew-wheeler-46134849_professors-that-follow-me-i-am-happy-to-activity-7446160904217407488-CXcZ         |
| 1    | 918   | https://www.linkedin.com/posts/andrew-wheeler-46134849_i-have-used-claude-code-the-longest-probably-activity-7447248077435920385-Ym8A    |
| 1    | 876   | https://www.linkedin.com/posts/andrew-wheeler-46134849_gio-has-a-new-post-out-on-examining-confidence-activity-7448697613513740289-hObZ  |
| 1    | 1959  | https://www.linkedin.com/posts/andrew-wheeler-46134849_the-mythos-technical-blog-post-on-its-cybersecurity-activity-7449059395071709184-UJOC  |
| 1    | 2201  | https://www.linkedin.com/posts/andrew-wheeler-46134849_for-folks-that-use-jupyter-notebooks-one-activity-7449422388691243008-Twxn        |
| 1    | 626   | https://www.linkedin.com/posts/andrew-wheeler-46134849_one-of-the-recommendations-i-have-in-the-activity-7450147165781426177-vceO        |
| 1    | 333   | https://www.linkedin.com/posts/andrew-wheeler-46134849_the-term-agent-is-almost-always-used-as-activity-7450509557677625344-42Ze         |
| 1    | 5787  | https://www.linkedin.com/posts/andrew-wheeler-46134849_agent-based-systems-require-bad-python-code-activity-7450871941458190336-gzSl     |
| 1    | 468   | https://www.linkedin.com/posts/andrew-wheeler-46134849_broadly-there-are-two-types-of-agent-based-activity-7451234329390678016-ZU1h      |
| 1    | 1267  | https://www.linkedin.com/posts/andrew-wheeler-46134849_i-get-periodically-asked-what-is-the-best-activity-7451596716354707456-aFMF       |
| 1    | 346   | https://www.linkedin.com/posts/andrew-wheeler-46134849_the-saying-a-picture-is-worth-a-1000-words-activity-7451959111132299264-Tk7o      |
| 1    | 480   | https://www.linkedin.com/posts/andrew-wheeler-46134849_it-is-important-to-have-independent-benchmark-activity-7452318150701953024-ftcM        |

I would have expected a multiplier (e.g. typically 3k views, now you have 6k or 9k views per post). So you could nitpick that I have differential timing for the posts, and the pre-premium posts have some contamination (if they promoted my older posts when I activated Premium). But those are not large enough to make a difference in my findings relative to what I expected.

The posts are quite comparable in content, mostly focused on my book and LLMs. It is possible my audience is oversaturated with that content, but I think it is just as likely that LinkedIn Premium doesn’t really promote your work to any substantive extent. (I have additionally obtained more followers in this period, so that should bias the results to have more views, not less.) At least here there is no evidence I should continue to pay $20 a month to increase my reach on LinkedIn.

Posts are bursty, and in the end I have very little ability to forecast what will or will not be popular. In the pre-period, my most popular post was on a blog post I did on log-probabilities (30k views). I definitely try to post more technical stuff on LinkedIn than the typical social media influencer, so that limits the reach.

I also had a rage-bait post on professors should teach python and not R with just under 30k views. (That was a bit of social media manipulation – have a controversial opinion that divides people, you get a bunch of thumbs up and a bunch of comments.) I do not have that many potential rage-bait post topics!

In addition to this, I also did the month for free for LinkedIn Premium for my business Crime De-Coder page. The same with my business page, I did not see any increased views, increased followers, etc.

Profile Views

Although I have not seen LinkedIn explicitly say Premium boosts your posts (besides actually paying for advertising), I have seen LinkedIn explicitly advertise that Premium profiles get more views:

So how do profile views look? I did get more the week I signed up, but it was trending upward previously, and reverted to the trend after week one anyway. (A few days short, I cannot access the chart week by week since turning off Premium.)

For a bit of background, I spent most of my time posting on my LinkedIn business Crime De-Coder page, and only posted on my personal page maybe once or twice a month. But since publishing LLMs for Mortals (in February of 2026), I have posted more on my personal. Which you can see increased my profile views before I signed up for Premium.

Likely the past additional profile views are for that rage-bait Python vs R post that was popular, not due to anything Premium did.

This appears to be extremely misleading advertising on LinkedIn’s part. If they just look at Premium vs not, it is likely Premium users are more active. This should just say the explicit “boost” profile views get, like ranked higher in searches.

$100 ad credit

With premium, you get $100 ad credit for posts a month. I used this to boost my original LLM for Mortals launch post, which was stale at that point and not accumulating any additional views.

The metrics on the post were as LinkedIn said they would be. Despite having 80+ likes when I first created it, the post only had 3700 views. Spending $100 on the credits got me an additional ~3500 views and supposedly ~50 additional website clicks. (I am confused how this is calculated, as I can see the actual link in the post was clicked fewer than 10 additional times with the campaign.)

I knew going in that adverts on LinkedIn are not a net benefit given my book purchase conversion rates. What I will call “high trust” referrals, I have something like a 1/100 purchase rate for the book. For other mediums, it is more like 1/1000. As far as I can tell, these seem pretty typical for a higher dollar value book purchase ($50+).

I have debated on setting the purchase price for the epub to much lower. $50 is in line with current offerings from O’Reilly, and in my informal demand curve tests is where I think it should be. But I don’t think any realistic conversion rate would make LinkedIn advertising make sense for my book.

For reference for influencers though, this gives a rough estimate comparable to LinkedIn’s direct advertising. Basically my average post is worth $100 according to LinkedIn. I only have around 3k followers currently on LinkedIn, so I imagine folks with followings 10x that can likely do direct advertisements to their audiences for more like $1k and up.

Wrap Up

I still think LinkedIn is the best social media site currently to promote my work and business. It is not just about the raw view counts, but also about conversion to people buying my book or reaching out for additional consulting gigs.

I will continue to use LinkedIn for this, but paying for a Premium LinkedIn account does not appear to be worth it for these reasons. Even if the views were increased, it is possible that they are not good connections for these end goals.

There are additional things you get with Premium (can send cold messages to people you are not connected to, supposedly higher priority when applying to jobs). Those are maybe worth the $20 a month for some people. But focusing on what LinkedIn advertises for “boosting” your posts and profile, I did not personally see any evidence that would justify spending even $1 a month for the Premium features.

Job Advice Resources page

Minor update, I have created a page, Job Advice Resources to cumulatively list all the materials I have written on advice for social scientists and crime analysts looking to pivot into private sector tech roles.

I still get maybe ~2 folks a month ask for advice, and I am always happy to chat. I wish PhD granting institutions took this more seriously (it only takes minor changes to better prepare students).

If you are an administrator of a PhD program and actually care about getting your students jobs, also feel free to reach out and I am happy to discuss how I can help.

Stop Teaching R. Teach Python.

There has been a slight transition in social science teaching since I have been a student and professor over the past ~15+ years. In the aughts, it was still common to teach students in legacy, closed source statistical software (SPSS, SAS, and Stata). When I was a PhD student in criminal justice at SUNY Albany, we had a specific class to learn SPSS, although most of the rest of the quantitative courses used Stata.

The R programming language has likely usurped the use of the closed source languages in social science education after the aughts though. (I do not have hard data, but that is my impression seeing what colleagues are using and what they teach in classes.)

I am familiar with all of the major statistical programs (I have written an R package, and you can see this blog for many examples of SPSS and a few for Stata). If the goal in coursework is to teach your students skills relevant to help them get a job, academics in social science institutions should teach their students Python. The current job market for quantitative work is dominated by Python positions.

To be clear, I am not fundamentally opposed to closed source programming languages (there are scenarios where SPSS/SAS make more sense than Hadoop systems I have seen, also if you are a GIS analyst you should learn ESRI tools). This is purely just an observation given the current private sector job market – focusing primarily on Python makes the most sense for social science students.

As an experiment, I went onto LinkedIn and did a search for “data scientist”. Your results will differ (mine are tailored to the Raleigh area, and also includes more senior positions), but here is a table of the positions that came up on the first page, and a quick summary of the tech stacks they require. While this is not a systematic sample, it gives a reasonable snapshot of current expectations.

| Company             | Job Title                           | Tech Stack                                           | URL                                            |
|---------------------|-------------------------------------|------------------------------------------------------|----------------------------------------------- |
| Google              | Data Scientist (Google Voice 2)     | Python, R, SQL                                       | https://www.linkedin.com/jobs/view/4387751995/ |
| Deloitte            | AI Specialist                       | None specified                                       | https://www.linkedin.com/jobs/view/4376183670/ |
| Ascensus            | Principal Analytics                 | R, Python, SQL, GenAI/LLM                            | https://www.linkedin.com/jobs/view/4380164400/ |
| EY                  | AI Lead Engineer                    | Python, C#, R, GenAI/LLM                             | https://www.linkedin.com/jobs/view/4385954762/ |
| PwC                 | GenAI Python Systems Engineer (2)   | Python, SQL, Cloud Platforms, GenAI/LLM              | https://www.linkedin.com/jobs/view/4373604638/ |
| Affirm              | Senior Machine Learning Engineer    | Python, Spark/Ray                                    | https://www.linkedin.com/jobs/view/4326673670/ |
| Lexis Nexis         | Lead Data Scientist                 | Cloud Platforms, GenAI/LLM                           | https://www.linkedin.com/jobs/view/4316327742/ |
| EY                  | AI Finance                          | SQL, Python, Azure, GenAI/LLM                        | https://www.linkedin.com/jobs/view/4385085950/ |
| Korn Ferry          | Sr. Data Scientist                  | Python, R, Spark, AWS, GenAI/LLM                     | https://www.linkedin.com/jobs/view/4387433496/ |
| Deloitte            | Data Science Manager                | Python, Cloud                                        | https://www.linkedin.com/jobs/view/4304674642/ |
| First Citizens Bank | Senior Quant Model Developer        | Python, SAS, SQL                                     | https://www.linkedin.com/jobs/view/4365378242/ |
| First Citizens Bank | Senior Manager Quant Analysis       | Python, SAS, Tableau                                 | https://www.linkedin.com/jobs/view/4388131284/ |
| Jobot               | ML Solution Architect               | Python, Scala, Spark, AWS, Snowflake                 | https://www.linkedin.com/jobs/view/4384023540/ |
| Affirm              | Analyst II                          | SQL, Python, R, CPLEX/Gurobi, Databricks/Snowflake   | https://www.linkedin.com/jobs/view/4373303038/ |
| Red Hat             | Sr Machine Learning Engineer (vLLM) | Python, GenAI/LLM                                    | https://www.linkedin.com/jobs/view/4354827922/ |
| Alliance Health     | Director AI                         | Python (TensorFlow/PyTorch), Office Products, GenAI  | https://www.linkedin.com/jobs/view/4383011480/ |
| Nubank              | ML Data Engineer                    | Python, Ray/Spark                                    | https://www.linkedin.com/jobs/view/4376815752/ |
| Target RWE          | Senior Quant Data Scientist         | R                                                    | https://www.linkedin.com/jobs/view/4385293724/ |
| Siemens             | Senior Data Analytics               | SQL, Python, R, Tableau/PowerBI                      | https://www.linkedin.com/jobs/view/4377969531/ |
| Red Hat             | Sr Machine Learning Engineer        | Python, GenAI/LLM                                    | https://www.linkedin.com/jobs/view/4302769773/ |
| Lexis Nexis         | Director Data Sciences              | Python, R, GenAI/LLM                                 | https://www.linkedin.com/jobs/view/4387335028/ |
| Cigna               | Data Science Senior Advisor         | Python, SQL                                          | https://www.linkedin.com/jobs/view/4381766145/ |
| Thermo Fisher       | Senior Manager Data Engineering     | Fabric, PowerBI, Python, Databricks, Tableau, SAS    | https://www.linkedin.com/jobs/view/4372684009/ |

Of the positions:

  • 9/25 roles included R, but only one required R exclusively. The other 8 were Python/SQL/R
  • 22/25 included Python
  • 11/25 had a focus on Generative AI or LLMs

Python dominates R in the current job market for data science positions. Professors are doing their students a disservice teaching R, the same way they would be doing a disservice teaching their students to code in Fortran.

Another aspect I noticed for this – analyst type jobs not all that long ago really only expected Excel (and maybe SQL). Now even the majority of the analyst jobs expect Python (even more so than dashboard tools like PowerBI in this sample).

For individuals on the job market, I suggest going and doing your own experiment job search like this on LinkedIn to see the tech skills you need to be able to at least get your foot in the door for an interview. I expected GenAI to be slightly more popular (only 11/25), but there were a few other technologies sprinkled in enough it may be good to become familiar with to widen your potential pool (Cloud and Spark – I am surprised Databricks was not listed more often).

If you’re looking to build Python skills from scratch, I cover this in my book: Data Science for Crime Analysis with Python (can purchase in paperback or epub at my store).

If also interested in learning about generative AI, see my book Large Language Models for Mortals: A Practical Guide for Analysts with Python.

You can use the coupon TWOFOR1 to get $30 off when purchasing multiple books from my store.

Using Claude Code to help me write

Using LLMs to help you write is understandably a touchy subject for many. There is quite a bit of AI slop coming out now, as it is really easy to just have the LLM tools think for you and write superficially OK but ultimately garbage prose.

My recent book, LLMs for Mortals, I used Sonnet 4.1 to write the initial draft of the book (for around $5). My prior book took around a year, whereas I was able to finish this book in around two months. I definitely did a ton of copy-editing (maybe around 20-30 hours per chapter on average), but I believe around 50% of the book material is the original Sonnet generated prose.

LLMs are a tool – they can be used poorly, but I think they can be used quite well. Pangram, a tool used to detect AI writing, does not flag any of the passages in LLMs for Mortals as AI generated.

This blog post goes over my notes on how I used Claude Code to help me write (although it really is applicable to any of the current coding tools, like Codex or Gemini as well). As a meta-reference, this blog post is 100% written by myself directly, but I will link to a draft written using Claude Code later in the post for a frame of reference.

Copy Editing

First, even if you do not agree with having an LLM write for you directly, there is a use case that should be relatively uncontroversial – having an LLM take a copy-edit pass on your work.

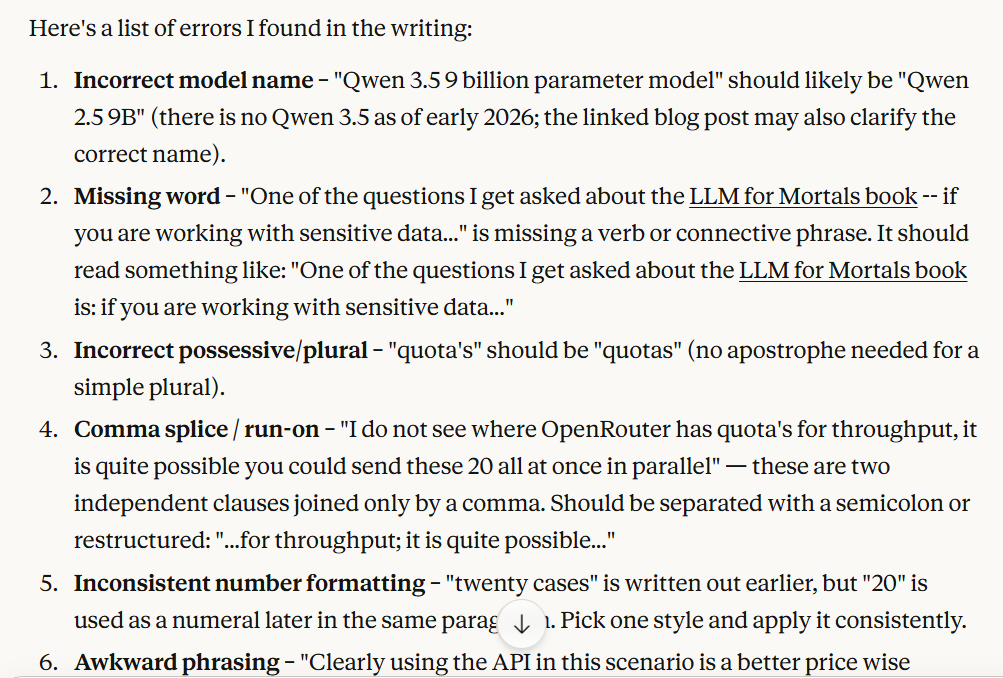
Here is an example I used this for recently, the blog post on Crime De-Coder goes over the benefits of using an API vs local LLMs. In this conversation, you can see my original draft, and the suggestions that Claude’s desktop tool (the free version) gave.

Again this is not really specific to Claude (this would have worked fine in ChatGPT as well). LLMs are good for not only spelling errors, but grammatical issues that spell check will not catch, as well as just more general copy-editing advice on the content.

One point of this – to replicate my setup, you need to write in plain text. Most of the things I write are in some form of markdown (plain markdown for blog posts, and Quarto for longer reports/books/etc). This makes it much easier to use the tools, especially the command line interface (CLI) tools like Claude Code.

Writing New Content

There are two big issues currently with LLM writing:

  • it is potentially wrong
  • current LLM writing has a particular style that is itself becoming noticeable

The first bullet, you need to review what it writes. It is much easier to have it write on content you are an expert in, so it is easier to review and spot errors. (It is the same current problem with using the tools to help you write computer code – they are boons for seniors but can write a ton of slop that more neophyte coders have a hard time spotting issues.)

The second bullet, having the style mimic your own, is what I am going to discuss here. It is worth understanding at a high level how generative AI LLMs work – if you ask “answer question X” vs “here is a book, …., answer question X” the LLM will generate a different response. The first part in the former prompt, “here is a book, …” is what is referred to the context. Current models have context windows (how large of a potential input) at around 500,000 words (technically they are around 1 million tokens, one word is often multiple tokens though).

You generally do not want to fill up the context window 100%, but 500,000 words is a very large number – just including text it would be multiple books. Another common prompting technique is what is called k-shot examples. It will typically go like

example input1: ...text... expected_output: ...blah...
example input2: ...diff text... expected_output: ...blah2...
....

This is what you place in the context window, then submit your usual prompt, and have the LLM generate the content. It is giving prior examples to help guide the LLM what you expect the final output to look like. This works the same way with writing – give the LLM prior examples of your writing to help it mimic your future style.

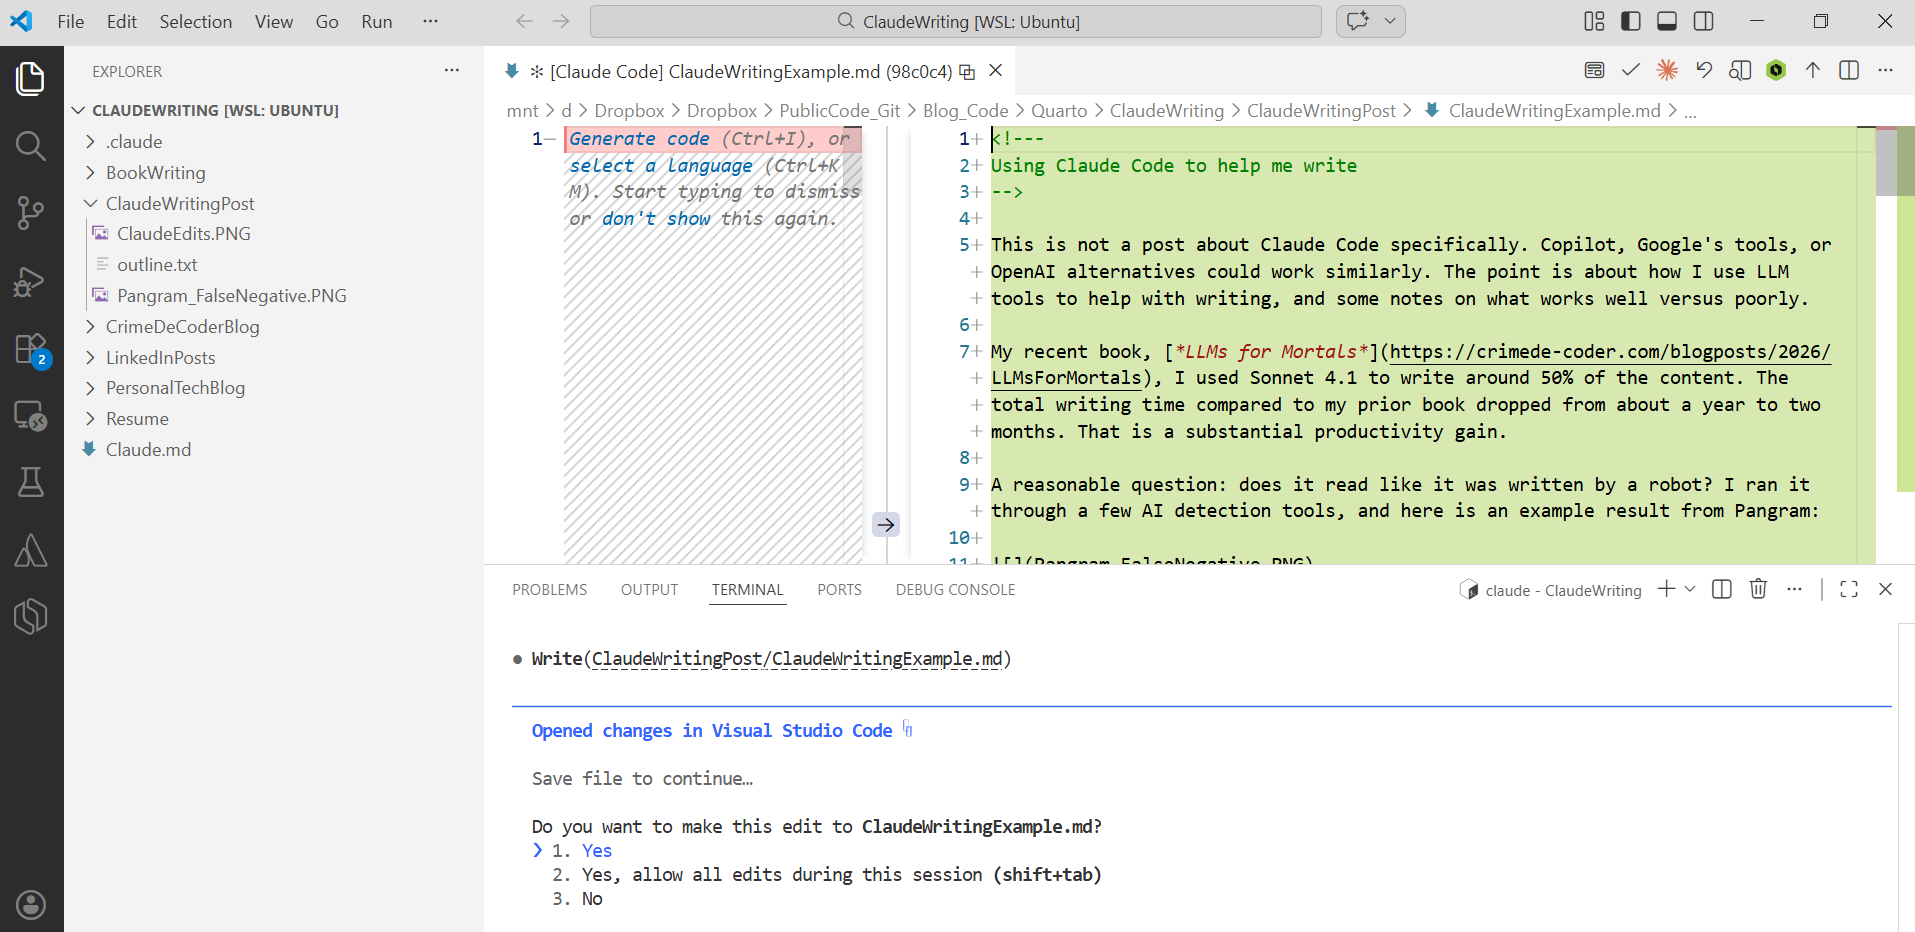
To keep it simple, I have created an example on github to follow along. Basically just have your prior writing (in text!), and then ask Claude Code something like:

review my prior blog posts in folder /blogposts, I am going to have you write a new blog post on topic X given the outline *after* you review the text

Then after your prior work is in the context window, feed the LLM an outline for what you want to write. In this example, I put the outline in an actual text file and said:

In the ClaudeWritingPost folder, review the outline.txt, then create a new md 
file, called ClaudeWritingExample.md, filling in the sections based on the 
outline

Claude Code will then go and review the text file with the outline and write the post. In the github repo I have my original outline for this same post, so you can see side-by-side.

You can technically write custom commands and skills with Claude Code (or the other CLI tools) to save the steps of typing two prompts, but to keep it simple for folks I am just showing the two steps manually. It is really just those two steps – get your prior examples into the context window, and then feed an outline for what else to write.

In the Github repo you can see some additional Claude.md files – these are files that include additional instructions. A common one I say is “do not include emojis”. LLM writing also tends to be verbose and have excessive lists. So I have instructions to avoid those as well.

The written blog post is not bad – I would suggest to go and read it as a proof of concept (I exported the session, can see it cost around fifty cents). Part of the reason I do not typically worry about blog posts is that I often add in things/change things in the process of writing. So you can see my personally written post is longer and has a few more elements.

So when would you use it? Technical writing, like writing tutorials in python, it works very well. Hence I could have it write the first pass on my LLM book and keep 50% of the content. I may use it for blog posts in the future (if I felt compelled to write something every day). But will not take that plunge for now.

For longer pieces, like an entire paper or a book, I suggest to not only make a detailed outline, but to also have the LLM write it in smaller sections. This both helps with reviewing the content, as well as to keep the LLM on track if you make edits/changes as you go. (Longer conversations it is more likely to degrade and make repeated errors.)

An Extra Note About Citations

I am not writing academic papers much anymore, but another fundamental problem with LLM writing is hallucinating citations. If you write in text markdown files, my suggestion is fairly simple – have the papers you want to cite in a bibtex file, and in-line in markdown, only cite papers in the form:

Citation, @item1 says blah [@item1; @item2]. For a specific page quote [@item1 p. 34-35].

The way I write my outlines, it typically is like write a paragraph about X, cite papers a,b,c. So my personal style of progressively filling in an outline works well with LLMs.

So this presumes you already have a list of papers (and are not using the LLM to dynamically write your lit review based on papers you have not read). Next time I actually need to write an academic paper, I may write up an MCP tool to query Semantic Scholar’s API and create a nice bibtex file.

But the solution here is again you need to review the output for accuracy. People without these tools are lazy and cite things they have not read already, so that will continue to happen (the tools just make it easier). Those that figure out how to use the tools appropriately though can be much more productive writing.

Year in Review 2025 and AI Predictions

For a brief year in review, total views for the two different websites have decreased in the past year. For this blog, I am going to be a few thousand shy of 100,000 views. (2023 I had over 150k views, and 2024 I had over 140k views.) For the Crime De-Coder site, I am going to only get around 15k views.

Part of it is I posted less, this will be the 21st blog post this year on the personal blog (2023 had 46 and 2024 had 32 posts). The Crime De-Coder site had 12 blog posts, so pretty consistent with the prior year. Both are pretty bursty, with large bouts of traffic coming from if I post something to Hacker News I can get 1k to 10k views in a day or two if it makes it to the front page. So the 2024 stats for the crime de-coder was a few of those Hacker News bumps I did not get in 2025.

Some of it could legitimately be traditional Google search being usurped by the gen AI tools. This is the first year I had appreciable referrals from chatgpt, but they are less than 1000. The other tools are trivial amount of referrals. If I worried about SEO more, I would have more updating/regular content (as old pages are devalued quite a bit by google, and it seems to be getting more severe over time).

I have upped my use of the free tools quite a bit. ChatGPT knows me pretty well, and I use Claude Desktop almost every day as well.

An IAM policy scroll is more of a nightmare, and I definitely ask more python questions than R, but the cartoon desk is pretty close to spot on. I am close to paying for Anthropic subscription for Claude code credits (currently use pay as I go via Bedrock, and this is the first month I went over $20).

What pages on the blog are popular I can never be sure of. My most popular post last year was Downloading Police Employment Trends from the FBI Data Explorer. A 2023 post, that had random times where it would have several hundred visits in a short hour span. (Some bot collecting sites? I do not know.) If it is actual people, you would want to check out my Sworn Dashboard site, where you can look at trends for PDs much easier than downloading all the data yourself!

One thing that has grown though, I do short form posting on LinkedIn on my crime de-coder page. Impressions total for the year is over 340k (see the graph), and I currently am a few shy of 4400 followers.

LinkedIn is nice because it can be slightly longer form than the other social media sites. I would suggest you follow me there (in addition to signing up for RSS feeds for the two sites). That is the easiest way to follow my work.

I also took over as a moderator of the Crime Analysis Reddit forum, it is better than the IACA forums in my opinion, so encourage folks to post there for crime analysis questions.

Crime De-Coder Work

Crime De-Coder work has been steady (but not increasing). Similar to last year had several consulting gigs conducting crime analysis for premises liability cases (and one other case I may share my opinions once it is over), and doing some small projects with non-profits and police departments.

One big project was a python training in Austin.

The Python Book (which I also translated to Spanish/French), had a trickle of new sales. 2024 had around 100 sales and 2025 had around 50 sales. It is close to 2/3 print sales and 1/3 epub, so definately folks should have physical prints if you are selling books still.

Doing trainings basically makes writing the book worth it, but I do hope eventually the book makes it way into grad school curriculum’s. (Only one course so far.) I have pitched to grad schools to have me run a similar bootcamp to what I do for crime analysts, so if interested let me know.

The biggest new thing was Crime De-Coder got an Arnold Grant. Working with Denver PD on an experiment to evaluate a chronic offender initiative.

At the Day Gig

At my day gig, I was officially promoted to a senior manager and then quickly to a director position. Hence you get posts like what to show in your tech resume and notes on project management.

One of the reasons I am big on python – it is the dominant programming language in data science. It is hard for me to recruit from my network, as majority of individuals just know a little R (if you were a hard core R person, had packages/well executed public repo’s, I could more easily think you will be able to migrate to python to work on my team).

So learn python if you want to be a data scientist is my advice (and see other job market advice at my archived newsletter).

AI Predictions

At the day gig, my work went from 100% traditional supervised machine learning models to more like 50/50 traditional vs generative AI applications. The genAI hype is real, but I think it is worthwhile putting my thoughts to paper.

The biggest question is will AI take all of our jobs? I think a more likely end scenario is the AI tools just become better at helping humans do tasks. The leap from helping a human do something faster vs an AI tool doing it 100% on its own with 0 human input is hard. The models are getting incrementally better, but I think to fully replace people in a substantive way will require another big advancement in fundamental capabilities. Making a human 10x more productive is easier and still will make the AI companies a ton of money.

Sometimes people view the 10x idea and say that will take jobs, just not 100% of jobs. That is a view though that there is only a finite amount of work to be done. That assumption is clearly not true, and being able to do work faster/cheaper just induces demand for more potential work. The example with calculators making more banking jobs, not less, is basically the same example.

One of the critiques of the current systems is they are overvalued, so we are in a bubble. I do not remember where I read it, but one estimate was if everyone in the US spent $1 a day on the different AI tools, that would justify the current valuations for OpenAI, Anthropic, NVIDIA, etc. I think that is totally doable, we spend a few thousand a workday at Gainwell on the foundation models for example for a few projects, and we are just going to continue to roll out more and more. Gainwell is a company with around 6k employees for reference, and our current AI applications touch way less than 1k of those employees. We have plenty of room to grow those applications.

It is super hard though to build systems to help people do things faster. And we are talking like “this thing that used to take 30 minutes now takes 15 minutes”. If you have 100 people doing that thing all the time though, the costs of the models are low enough it is an easy win.

And this mostly only holds true for knowledge economy work that can be all done via software. There just still needs to be fundamental improvements to robotics to be able to do physical things. The tailor’s job is safe for the foreseeable future.

The change in the data science landscape to more generative AI applications definitely requires social scientists and analysts to up their game though to learn a new set of tools. I do have another book in the works to address that, so hopefully you will see that early next year.