Why academics should self publish textbooks

I have self-published my two textbooks, Data Science for Crime Analysis with Python, and Large Language Models for Mortals: A Practical Guide for Analysts with Python. I have written about my set up previously, long story short use Quarto to compile the books to epub and a nice PDF, and then use LuLu for print on demand.

I figured a blog post on why I think all academics should take this route when publishing textbooks is in order though.

Reason #1 – you can set the cost.

Most textbooks are ridiculously overpriced. My two books I sell at print prices of $50 and $60. These are textbooks that are over 200 pages in a larger letter paper size. If they were the smaller size, they would be 400+ pages, and priced for print well over $100 (and possibly over $200). The actual print costs for each of my books are around $20 and $30 (and then $6 to $10 for shipping). And of course selling the epub is basically zero cost.

Many professors write their own textbooks because they teach a course that does not have a standard text. (Most are not doing it to make a buck.) You can make a buck if you want, and still sell the books for less than half of what an academic publisher would charge for the book.

So without a coupon, I make about $30 when I sell a print version of either of my books. (If professors adopt one of my books for the course, I give coupons so I only make $10 margin per book, either print or epub.)

To be clear, I do not suggest writing your own textbook to fleece your students. But if you do write a good textbook for a course, why not make it more broadly available to everyone?

Margins for professors selling a book through a traditional publisher are typically around $1 per sale. Again I sell my books for less than half of what an academic publisher would sell them for, and make closer to $30 per sale on average.

Reason #2 – you have full control over the content and layout.

My books are letter-sized (8.5 by 11 inches), not the more typical 6 by 9 inches. This is based on personal preference, one I think many will share when writing technical textbooks. The code snippets in the book look much nicer with the larger pages – I can have larger code-snippet sections. It also allows me to have larger images, without odd artifacts with the ragged bottom for the print version.

I have posted my Quarto and LaTeX notes on my book set up. If you are not familiar with Quarto, you write your book in plain text Markdown, and then have a tool compile the book to the different end formats. For those not familiar, Markdown looks like:

# This is a title

A section describing something ...

![An image caption](Figure1.png)

So you write in a plain text, and then have a tool turn the plain text into different formats. For print, you will make a PDF version to send to the service that prints the book. You can also make an epub (or just share the PDF) as well, or make an HTML website. (Jacob Kaplan’s Crime by the Numbers: A Criminologist’s Guide to R is a good example website that also has a book, which costs over $100 for the print version.)

One of the points I have never seen another editor make – epubs should be formatted differently than print. I use different fonts for the different versions of my books. This is easily possible with just changing the meta-data in Quarto (and would work the same if just using Pandoc to directly convert as well, this advice is not specific for those writing coding books).

Reason #3 – you can update the content as much as you please.

If you want a textbook, printed through a traditional academic publisher, it would take around a year to go through the motions of updating the draft, getting editor feedback, and going into print. You can do updates as fast as you want when self-publishing. You spot an error, you can have an errata and simultaneously fix it for all future versions as fast as you can do the edits.

Many academics do not care about this very much, but when writing textbooks that include code, I do. Code can go bad, particularly when writing about contemporary topics like large language model APIs.

Pre-empting some reasons to not self-publish

Now some will read the above statements and (reasonably) think those benefits can be bad. It can be bad that you have full control over the layout, most people will not care. It could be bad you have the obligation to update the text yourself (without an intermediary copy-editor).

I have published two other textbooks through traditional academic publishers, and to be honest these things are not something you should value all that much. The amount of copy-editing you get from a traditional publisher is pretty minimal. If you read my description of markdown above and think, I don’t want to have to figure that out, just get a $20 subscription to OpenAI or Claude, give it the link to this blog post, and ask it to set your computer up for you. Even if you do not want AI to help you write (you should definitely use it as a copy-editor for slight grammar and spelling errors), this is worth your time.

There are two aspects that self-publishing are clearly worse though than going through a traditional academic publisher – distributing your book and potential prestige. For the prestige point, I am talking about academic textbooks (like those published by Springer, Wiley, Pearson, university presses, etc.). Most people do not consider them prestigious, but I have no doubt some fool Dean bean-counts those as publications for tenure and will discount self-published books. They should not, but I am sure some do. For the small number that have a fool for a dean, I am sorry about your current lot in life.

For distributing your textbook, it is easier to get a textbook in a university library through a traditional academic publisher. I go through the whole process of getting an ISBN, copyright, and submitting my books to the Library of Congress. So libraries can (and have when professors request it) made purchases of my textbook. I imagine if you publish a textbook with Wiley though they have standard ways to get books into libraries, go to conferences and have a stand, etc.

Ask a friend who has published a textbook the benefit of this next time you meet. They will tell you something like “I don’t know what you are talking about, I only sold 12 copies last year”. If you can get a For Dummies book, this is not the same as an academic publisher. The University of Punxsutawney press is not hustling to sell your book in Barnes & Noble.

So do your students and yourself a favor, self publish that textbook.

VerusCite is now $1, Crime De-Coder Store updates, CCJ Homicide Report, and some more AI papers

For several minor updates across my different projects. One, I have updated my Crime De-Coder store where I sell my books and software. Before, it was a WooCommerce site, which worked ok (pure GUI integration). But it was time for me to upgrade and have it directly integrated into my site.

It was a WooCommerce site before, which worked ok (pure GUI integration). But it was time for me to upgrade and have it directly integrated into my site. So now it is using the direct print API from LuLu for the books, and everything else is custom PHP code. Using Opus 5.5, this was just a day of tinkering. For several coupon codes:

  • LLMDEVS, $25 off LLM for Mortals epub
  • TWOFOR1, $30 off if you purchase any two books
  • SIXPRINT, $20 off LLM Mortals paperback
  • NEWSTORE, $20 off any of my Data Science for Crime Analysis book (paperback or epub, in any language)

VerusCite is now only $1 to review a paper. Between Luna 6.0 pricing and Perplexity fast web search being cheaper, it has brought costs down far enough for me to offer it at $1 per check.

Also VerusCite has its first retraction, a paper in Policing: An International Journal. Sign up and let your editor friends know about the tool!

The Council on Criminal Justice has released their report on the expert opinions on the homicide decline. I was invited, and thought it was well run. There was not much agreement on what caused the decline (which is difficult if not impossible in noisy crime data), but there was agreement on factors that likely did not contribute to the decline. Take this example of why I think increased firearm carrying is not a likely contributor to the recent homicide decline.

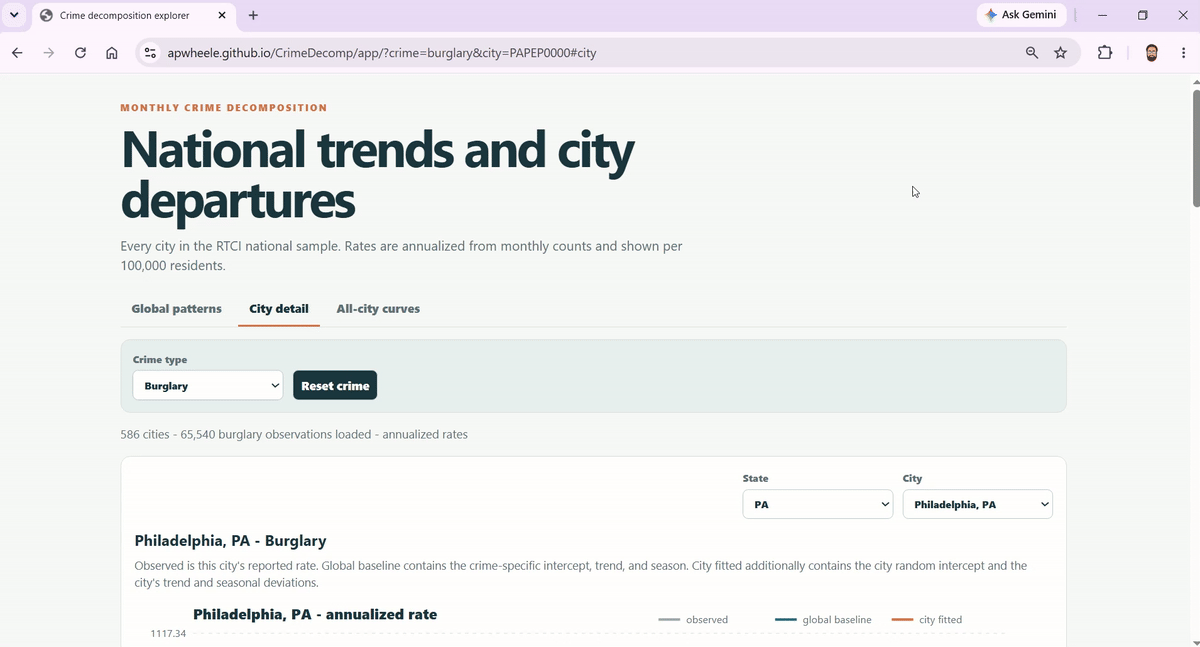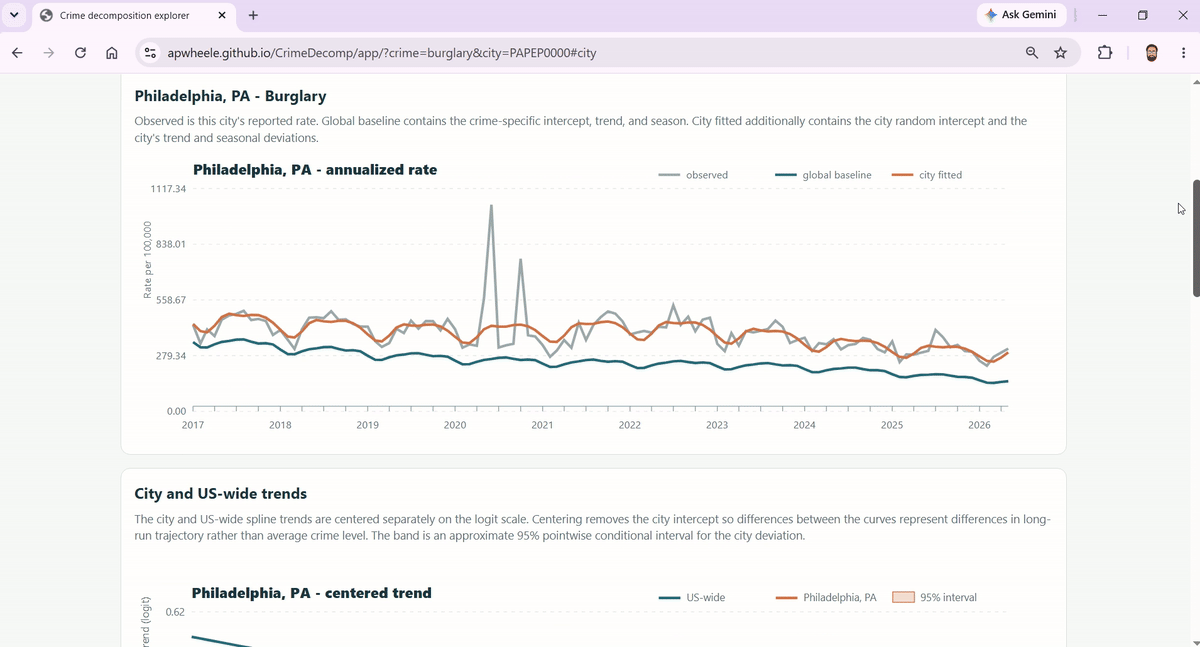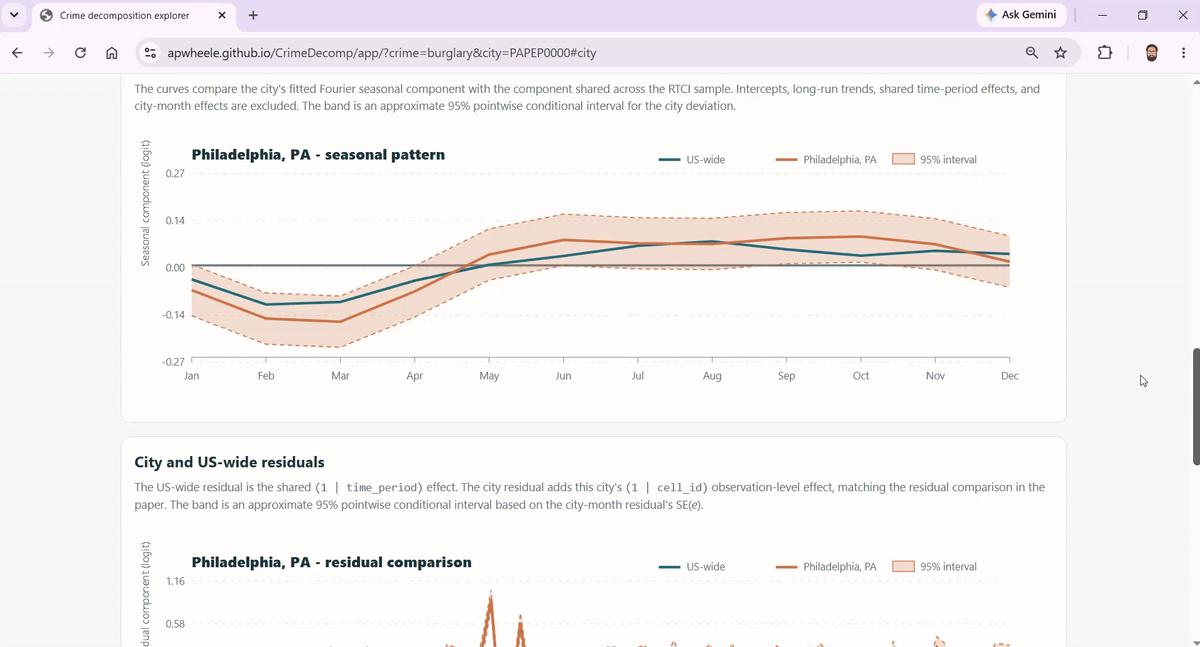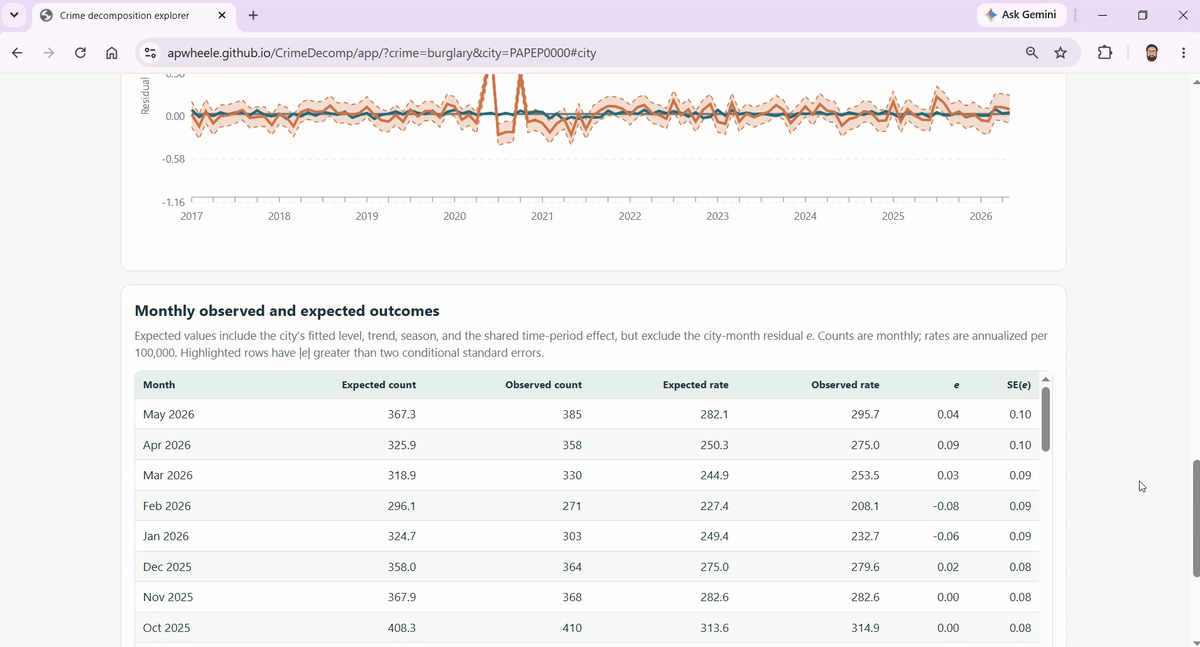
If you are interested in this report, I also made two different web apps to peruse different national level crime trends (based on Jeff Asher’s real-time-crime-index sample of 500+ cities across the US). The Crime Decomposition Explorer, where you can see a single city and compare their trends to the rest of the US. Or the Synth app, where you can conduct a synthetic control estimate for a specific city, timepoint, and crime type of your choosing.

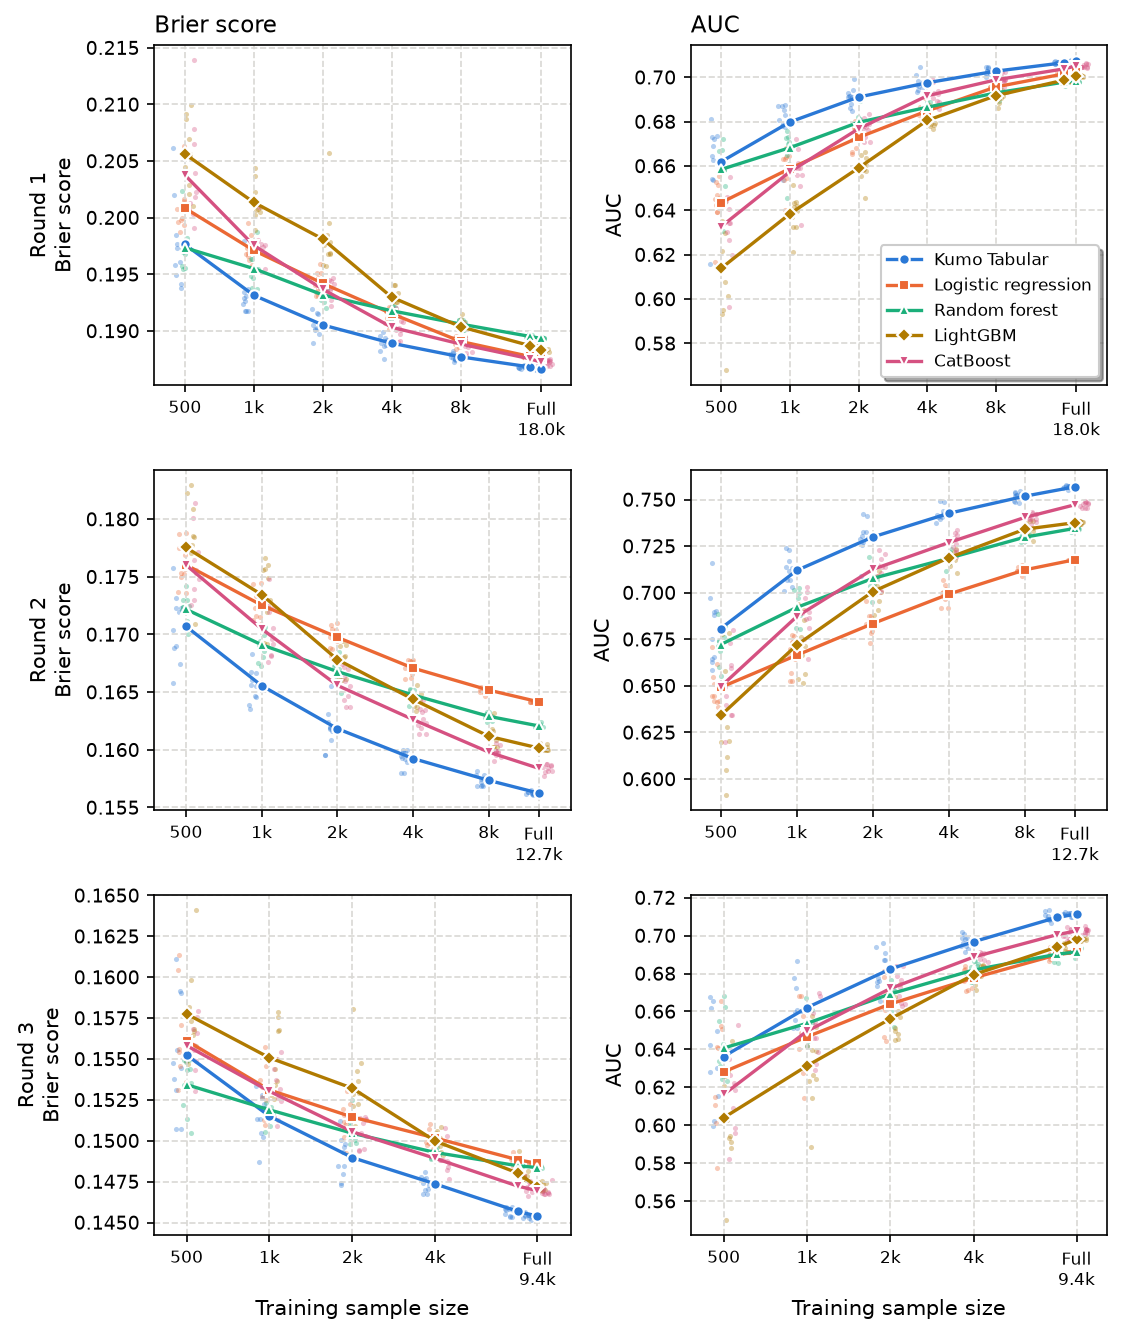
In continuing with my tests in having AI write whole papers, I have two additional ones. Using NVIDIA’s newest tabular foundation model Kumo, I show it would have done quite well in the NIJ recidivism competition without feature engineering. It basically would have placed on the large team leaderboard for the majority of the competition sub-categories.

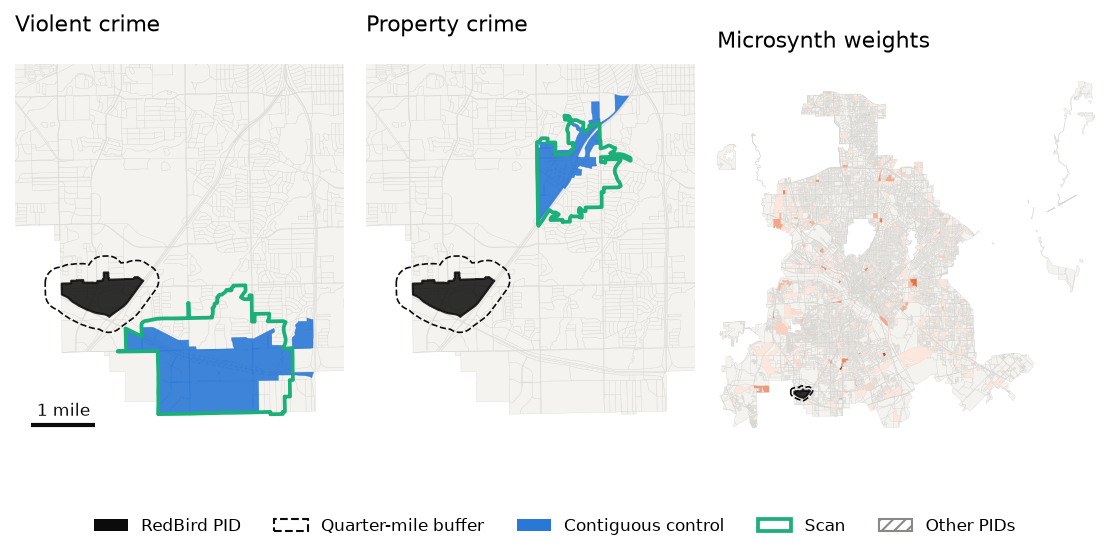
Another AI paper is developing a spatial scan technique to choose a control area for a place based crime intervention. This is a follow up to the WDD paper I wrote with Jerry – this is a way for an analyst to have a data driven approach to choose a control area that follows similar crime trends.

I do not like microsynth (it clearly is overfitting to the data), and in the pretty tame simulations I show the chosen control area is less biased.

I did actually have GrokBot upload one of my AI papers to crimrxiv – Fair and efficient spatial siting of public surveillance cameras. I may upload more of them at a later date, I am not 100% sure. (I am unlikely to spend the time to get them peer reviewed though; they will get more views on my blog and via crimrxiv than they would in a peer-reviewed publication.)

If you are interested in training, though, for your graduates or program, get in touch. I have been sending out emails to programs to encourage departments to pay for Python training or training on using LLMs. The current AI tools can (and should) definitely be used effectively and safely for social science research. Academics are just sticking their heads in the sand if they think AI cannot or should not be used to help with research and writing.

Adventures in using AI to write papers

Until recently I had only used the AI tools pay-as-you-go, but lately I have been experimenting with the $20 monthly subscription. So I ended up with extra credits to burn. I would periodically just set the AI tools on writing papers I have wanted to write for quite some time.

Here are some of those experiments. Of these, the Crime Decomposition paper is the only one I spent more than a day on. (And that was mostly because it was running models that originally took 10+ hours and then would fail, until I had it switch the model to one that was much faster.)


Optimal Search Paths – this is a project around drawing optimal search paths when you have a smooth surface where an object is likely to be found. It was motivated by a paper from Kim Rossmo on likely locations of a lost hiker based on cell tower pings and hypothetically using a drone to search Joshua Tree for that hiker.

CrimeDecomp – so this is an update of my monitoring volatile homicide paper, just extended to all major UCR crimes and the monthly data from Jeff Asher’s RTCI data hub. I made a cool website with data dashboards you should check out.

I have several different synthetic control related papers/apps. I have always thought the power to identify macro changes, especially with state-level designs, is far too low. I had Claude write a simulation to show this, SynthPower, as well as to show coverage for my conformal estimate (which is too low for the cumulative estimate, and hence it shows a few different ways to make that cumulative estimate better). I additionally made a nice app, SynthRTCI, where individuals can go and just do a synthetic control estimate for the RTCI data and time period of their own choice.

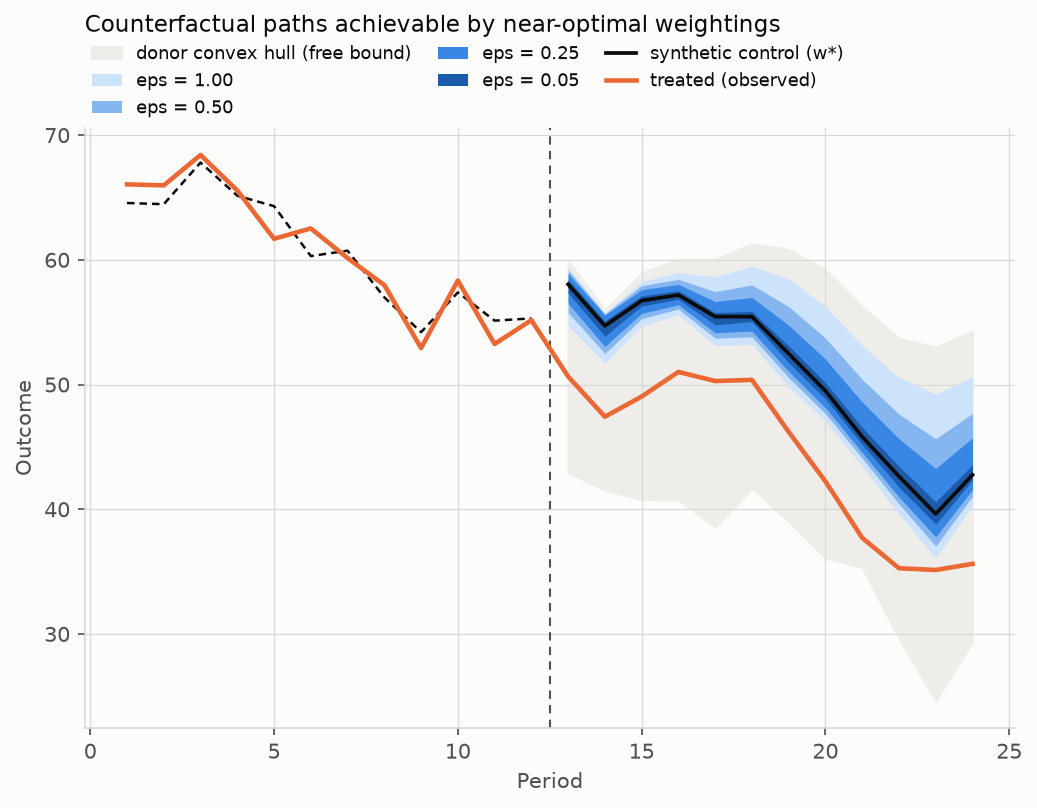
Because synthetic controls are underdetermined, I also had Claude write a paper using Manski-style ignorance bounds.

A while ago I showed how to use paired network stats and false discovery rate corrections to identify near-duplicate surveys. I had Claude write it up more formally in a paper, SurveyMatch.

And I have two different fairness paper ideas. One is to optimally site CCTV cameras with fairness constraints. The other is using conformal sets to equalize the false positive rate between groups, using the NIJ recidivism data as an example, Conformal Fairness.


Sitting down and thinking about it while writing this blog post, I could easily come up with another six papers. (Which maybe I will work on. I have more Claude credits over the next few weeks than I know what to do with, even on just the $20 subscription.)

These are ideas that, were I still an academic, I would pursue more seriously to be published. I would definitely need to spend more time cleaning up the prose (I would guess another 20+ hours rewriting, if not just having a grad student work on it). But the data/code are mostly good as is. And I do not claim that they are even novel (if I searched hard enough I could probably find prior work for these ideas not in criminal justice journals). But I am pretty sure I would be able to publish all of these ideas in mainstream or at least mid-tier criminology journals.

What does this mean long term for academics writing papers given that it is this easy to have AI go brr and do pretty detailed coding and write-ups? Some brief thoughts:

One, you still need a human to identify a good idea. These are ideas I have had in mind for years at this point. Here for example is the original prompt for the ConformalFair paper to check out the level of detail I provide. I then reviewed the output, went back and forth with Grok for a few tweaks, and in about an hour total had that paper.

I am skeptical you could use AI to come up with interesting paper ideas at this point, at least from what I have seen.

Two, peer reviewed papers were already mostly symbolic. With the ease of writing them, they will become even less important over time. What I have heard from criminology journal editors is that in the past year, submissions have basically doubled. I expect it to maybe double again in the coming year. The value in papers, though, is whether someone uses them to accomplish real things in the real world. So if I had a city working with me to identify camera locations, this work would be more relevant (I don’t have one, but feel free to hit me up if you want!).

Ultimately writing a paper is just like a tree falling in the woods: it only makes a difference if someone hears (and acts on) it. I am hoping academics can start to more highly value making a difference, as opposed to pumping out superfluous papers that no one reads.

Join CrimConsortium, ASEBP submissions open, VerusCite privacy, NACA Course

I have minor updates for several activities.

First, the American Society of Evidence-Based Policing is accepting submissions for its conference in spring 2027 at UPenn:

If you are a vendor interested in promoting some of your work at the conference, also feel free to get in touch. I serve on the committee that works with vendors and the committee that reviews proposals.

Second, I have updated several of the pages for Crim Consortium (roughly the nonprofit behind CrimRXiv).

For individuals, you should consider becoming a member to support the work Scott (and to a lesser extent myself) is doing on this. (We do not make money to be clear, just keeping the lights on.)

If you are a program head for a department (or involved in some other organization), you should consider becoming an institutional member. You get your own prioritized page (which is worth it just for the SEO for your group).

CrimRXiv has over a million pageviews per month at the moment. It is easily the best preprint server to post your work to for anything related to criminology at all. It is also the only preprint server that lets you upload your work in HTML format (you can upload a Markdown or LaTeX file as well and it turns the paper into HTML). So you can have embedded interactive graphics if you want, for example.

Third, VerusCite has a blog with the most recent post about How VerusCite Handles Privacy. For individuals running journals, I only submit the references to the LLMs, unlike other editors. Those LLMs are zero-data-retention, and I also do not see what you upload.

Journals should really be investing in my tool. Most journals would only take a few hundred per year at $2 per paper.

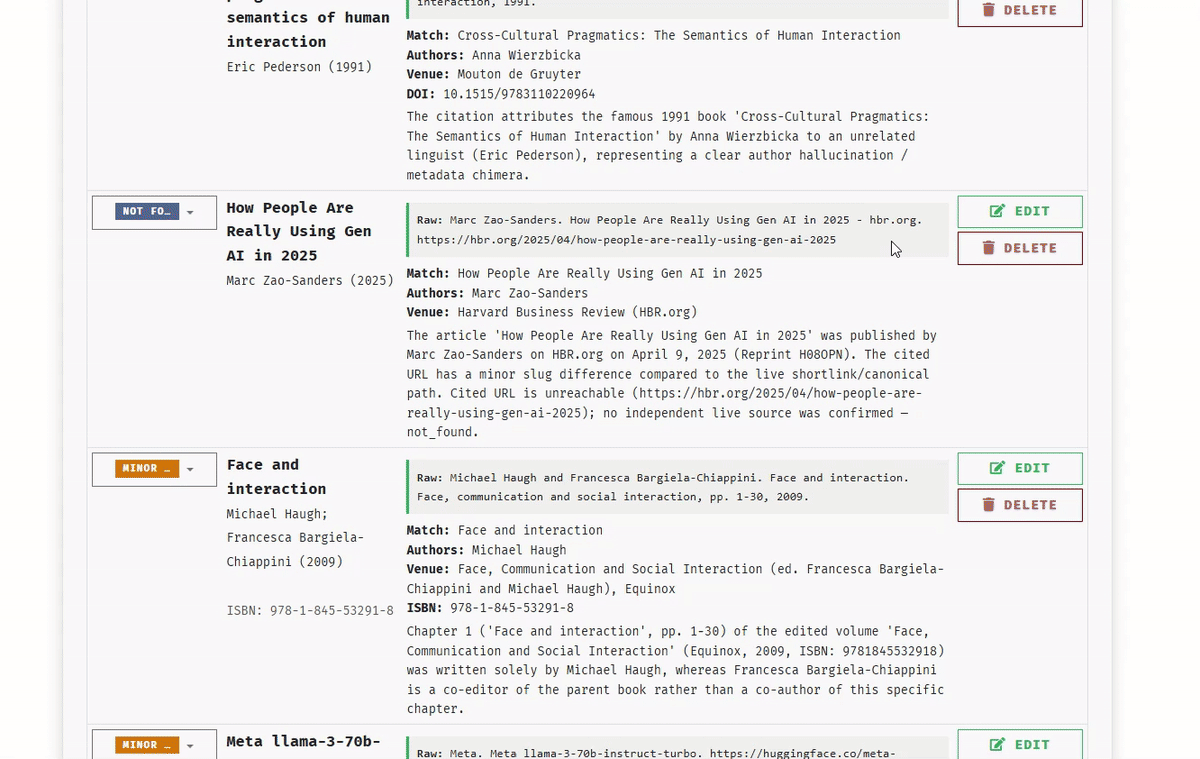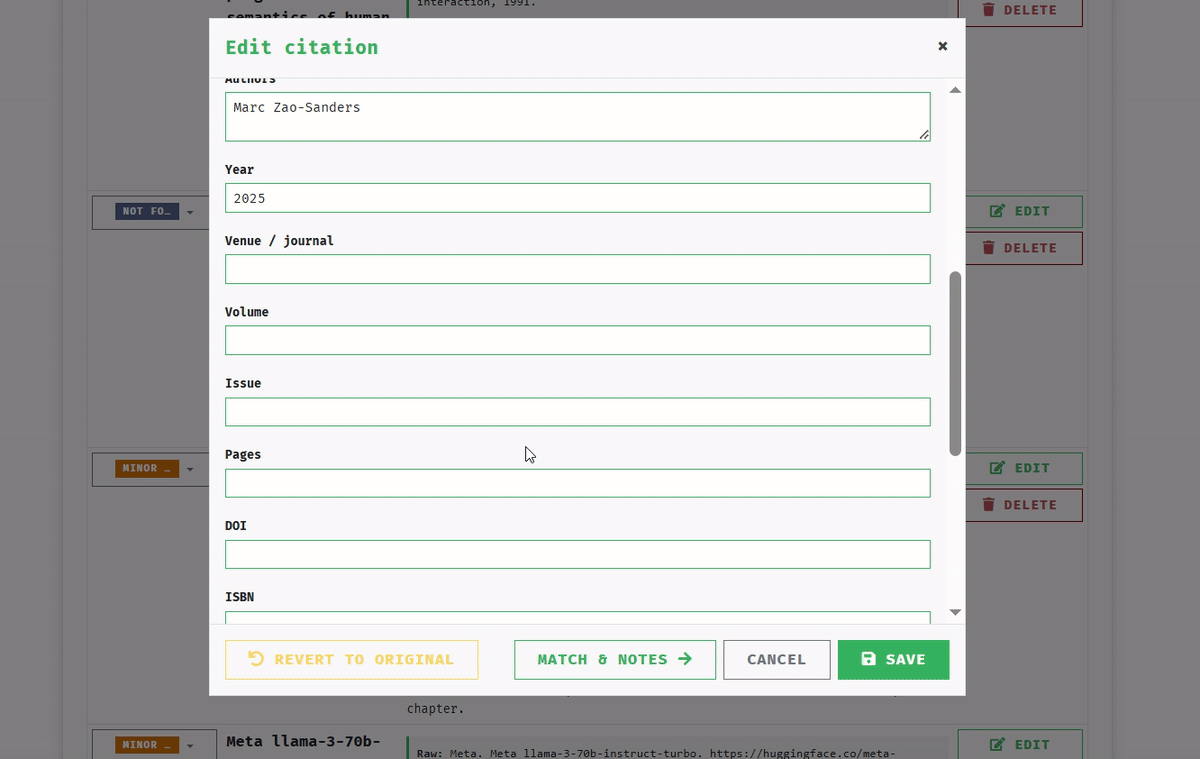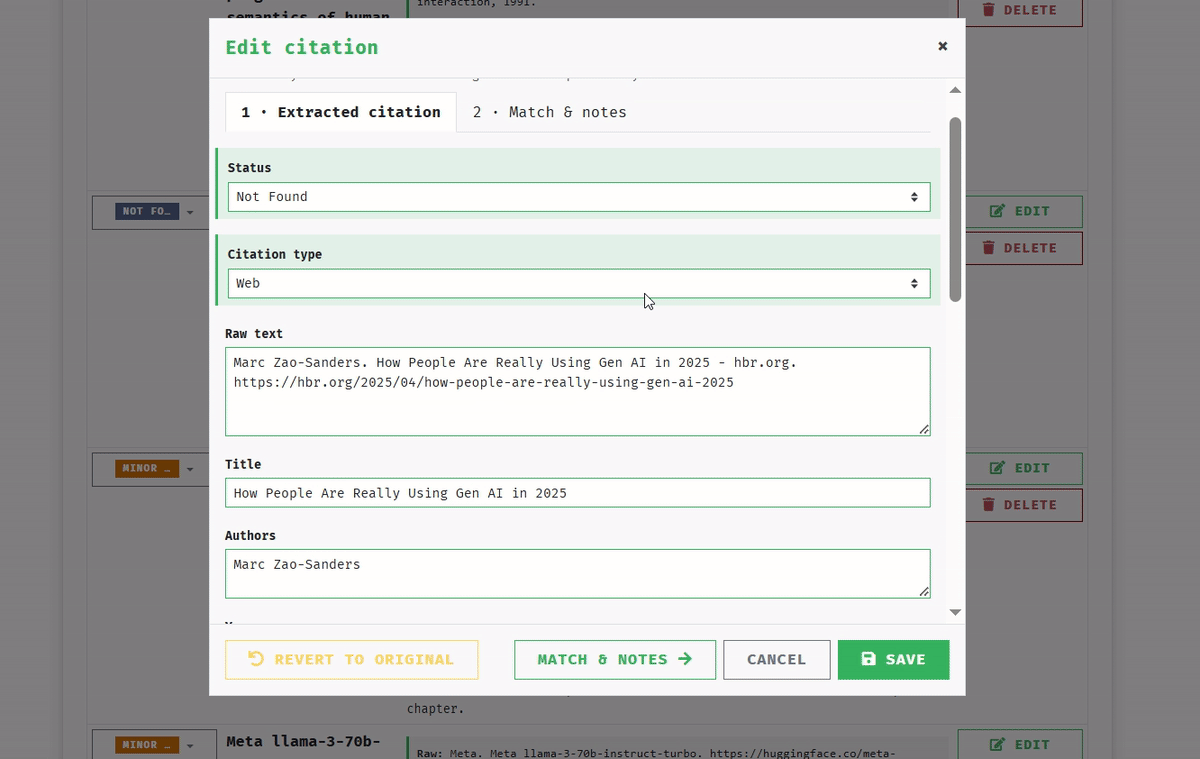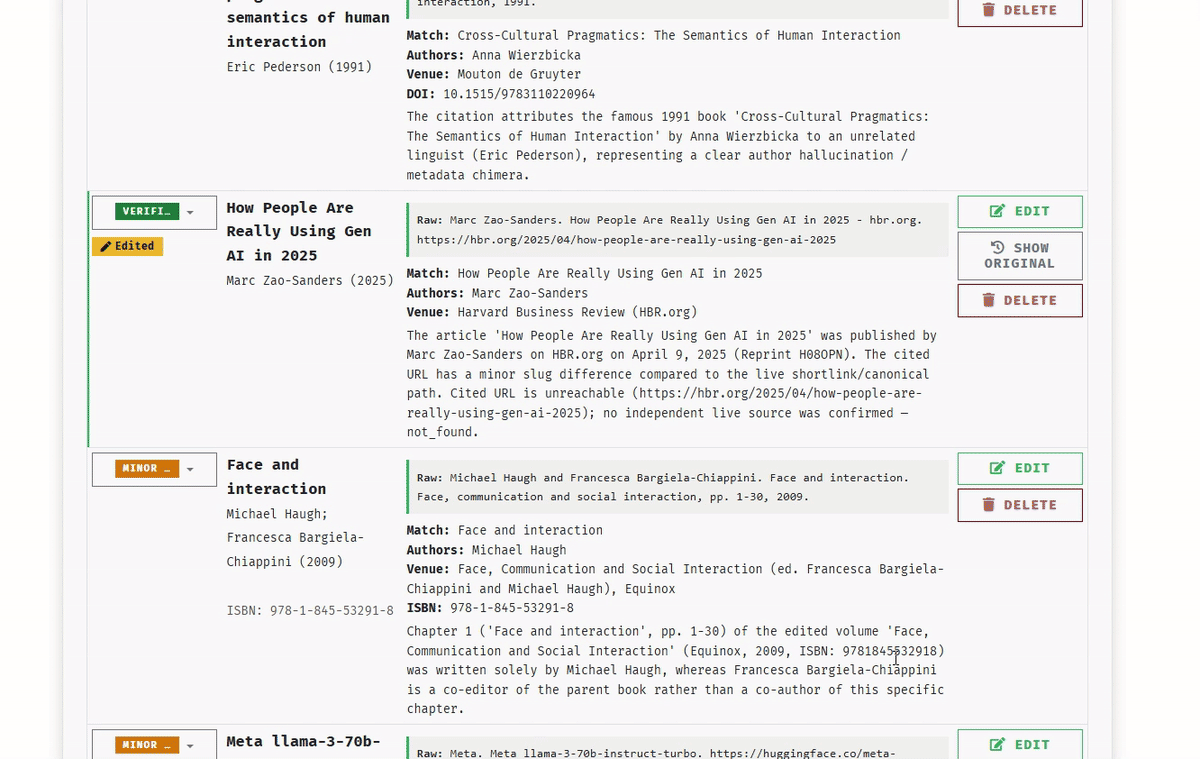
This is a major problem across science as a whole at the moment. The Hall of Hallucinations is up to 27 papers as of this writing, and I tend to add at least one a day.

Fourth, I have contributed a course to the new National Association of Crime Analysts called Basics of Python Programming for Crime Analysts.

This asynchronous course consists of bite-sized labs to go with my book, Data Science for Crime Analysis with Python. If you would like in-person training, get in touch, but this is much more economical for those interested in pursuing training on their own.

Crime De-Coder and VerusCite Updates

If you do not follow me on social media (X, LinkedIn), you likely have missed the different work I have been up to. So this is a remix of some of that, posted here for folks to follow along.

Crime De-Coder Blog

On the Crime De-Coder Blog:

I often debate whether to post things here or on the Crime De-Coder blog. So if you like my posts here, you should probably also follow Crime De-Coder. As you can see, it is a mix of recent technical and crime-analysis-related posts.

For the crime trends work, also check out my web app, where you can filter and compare cities relative to national trends (based on the Real-Time Crime Index data).

Note that I will be going to the Council on CJ working group on crime trends, on the causes of the homicide decline, in a few weeks, so let me know if you want to meet up.

VerusCite Updates

This is a newer one, but I have created a blog on VerusCite as well. Recent posts include:

And I have also made a Hall of Hallucinations, where I am putting my “hallucination of the day” articles moving forward.

I will be making some demo videos of VerusCite in the near future, but for a sneak peek, you can see I have spent quite a bit of time on the tool’s user interface. It is really intended to be human-in-the-loop.

I particularly want to get this in front of journal editors. It is really cheap ($2 a paper). It is totally feasible for journals to spend a few dollars to prevent these embarrassing results from being published.

Interest in an Actually Private Chat App?

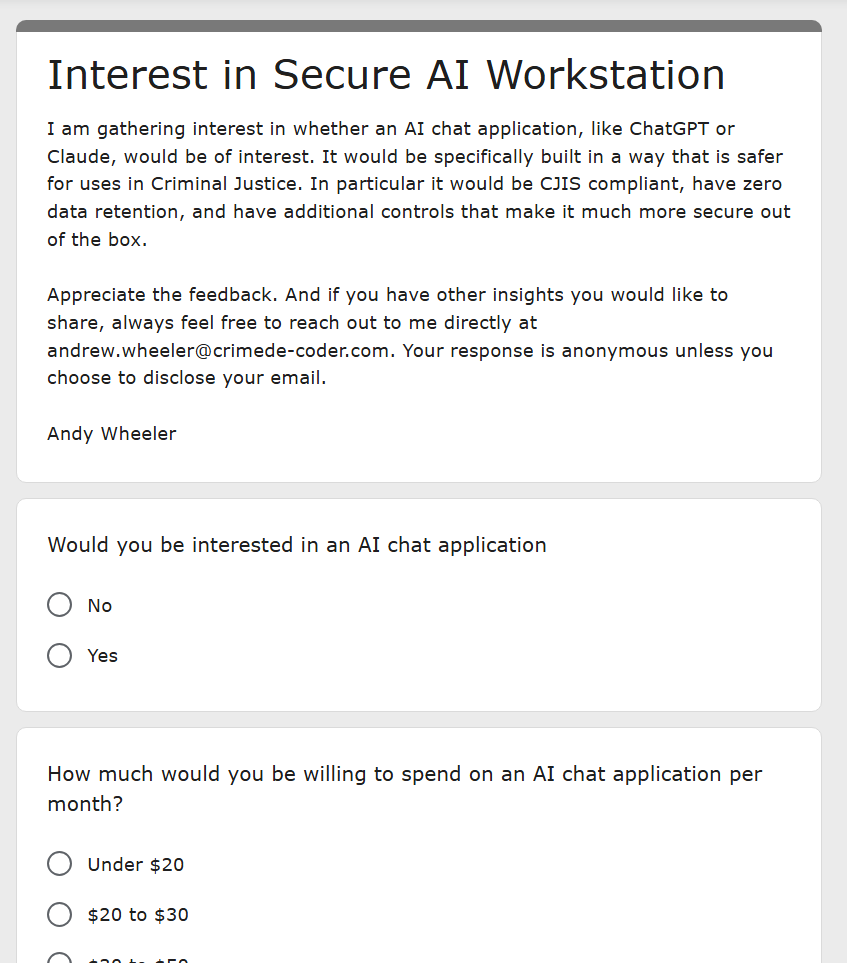
Final share today, with the news of an expert witness and their very embarrassing ChatGPT conversations coming to light, I opened up a survey to see if people are interested in an actual “safe” chat app that has zero data retention.

It used to be that if you paid for ChatGPT (or Claude), you could opt out of training. More recently, these companies have committed to retaining information for model safety, or because courts have told them they need to keep it. Mostly when calling the APIs directly, they are zero-data-retention by default (beyond a few minutes to keep the cache). So building a ZDR chat app is totally feasible.

See the survey I have opened up here, which asks if you are interested, price points, desktop/web-app, what you would use it for, etc. I do wonder if there will be more potential interest in state entities, since OpenAI and Anthropic are really dropping the ball here on whether people can trust them with sensitive information.

License Plate Reader Searches Should Require a Warrant

So while I work with police departments regularly, I think it is critically important that technology be used reasonably.

While this may be off-putting to some of my clients, I worked with the Institute for Justice as an expert witness in their trial Schmidt v City of Norfolk. (Any opinions herein are my own and not those of IJ, to be clear.) The gist of that case was whether searches of historically cached ALPR data (automated-license-plate-reader) constituted an illegal search.1

The judge ruled against plaintiffs in that case. Here is a quote from the judgment:

Consistent with Plaintiffs’ claims in this case and controlling precedent involving mass surveillance in public spaces, ALPR surveillance could become too intrusive and run afoul of [constitutional privacy standards] at some point. But when? While a definitive answer to that question is elusive, what is readily apparent to this Court is that, at least in Norfolk, Virginia, the answer is: not today.

The important point to note about this quote is “not today”. This will be a long winded post, but to try to keep it simple:

  • I think cameras will become ubiquitous in the foreseeable future. So the question is not if this data will require a warrant, it is when. It is going to happen eventually under current case law.
  • I think cameras are good, and can be used to reduce crime in a cost effective manner.
  • There is a difference between active flags (e.g. this car is stolen and it pings the PD when it drives past a camera) vs historical searches (e.g. look to see where license plate XYZ1000 was the last 30 days).
  • Requiring a warrant for historical searches will not seriously impede police investigations.
  • The current status quo of not retaining data is VERY BAD; it does not prevent illegal searches, and currently limits the utility of actually using that data for legitimate investigations.
  • Current standards to prevent abuse of the searching ALPR data systems are laughable.

Long story short in my opinion everyone would be better off if states just mandated warrant procedures through state statutes.

To try to not get too much into the weeds of what historically constitutes a search, I think the easiest place to start is via Carpenter vs US. So current US case law requires police departments to obtain a warrant to request cellular providers provide law enforcement with cell phone tower pings (cell-site location information, CSLI).

This deviated from historical precedent in requiring a warrant mainly because it was private companies that had the information. Before Carpenter, mostly it was argued you did not have a reasonable expectation of privacy if a private company could access the same data. The court in Carpenter basically made a determination that cell phone data was so comprehensive it justified a different standard – that you could track the whole of a person’s movements with the detailed CSLI data. And that this level of invasiveness violated a reasonable person’s expectation of privacy. Even if Google had all that info, you did not expect them to give it away.

This opinion was reaffirmed with the recent Chatrie decision (for geofence warrants, e.g. give me a ping for all cell phones in area X and datetime-range Y). Another relevant decision to be aware of is also Beautiful Struggle v Baltimore, in which searching historical aerial imagery via drones also constituted a search.

So this is why I am saying the question is when, not if, ALPR data will require a warrant. If a city happened to have a camera on literally every intersection (which I think will happen in the future), under current case law it would clearly be the same situation as you have for your cell phone data.

Cameras are Good

To be brief, again I mostly work with police departments in my career and was a former crime analyst. I do think ALPR cameras are good investments, mainly because they are cheap enough to have a reasonable return on investment. (Note I do not think this about all police tech, I am particularly critical of the price tag for acoustic-gun-shot-detection.)

So ALPRs are well under $3,000 per camera. The machine learning models, camera, and computation necessary to flag a plate when it passes can easily fit on current cell phones. (The harder part is powering the phone and protecting it from the elements.) ALPRs for the most part just take static images and then extract out the license plate (and for some vendors extract out additional information, like car make and color).

The overall evidence that ALPRs reduce crime is pretty meh at the moment (see my slides at a Wake Libertarian talk I did in 2024), but because they are so cheap they really only need to increase a few arrests per camera to likely have a positive return on investment.

It is pretty hand-wavy, as we do not have estimates for the value of increased clearances I find persuasive. But I think saying “I would pay $500 to help solve one case” is on the low side if anything. So a single camera if it helps catch just a handful of crimes a year is likely in my opinion to be a positive ROI.

I think cameras in all public spaces are going to happen. Imagine Ring comes out with a nicer camera system for homeowners that has more comprehensive views around your house and is just as cheap. And we will ultimately be safer for it. So even for folks advocating that cities do not pay for Flock, this is coming anyway in the near future.

Historical Searches vs Active Flags

ALPRs have been around a long time. The first ones I worked with at Troy, NY when I was an analyst were in-car cameras. Basically a go pro attached to the window that alerted when an officer drove by a stolen plate.

While ALPRs initial use was always pitched as this active flagging of stolen vehicles, they were used right away to retroactively search the historical locations of plates. They had a log of every plate, lat/lon, and timestamp of when that car passed a camera.

So imagine you are conducting an investigation of Joe Schmo, you know his license plate, and then you can type in his plate and see where his car passed a camera. Based on this information, same as CSLI data, you can basically trace where Joe went, where he repeatedly visited, where he likely slept, etc. (The first time I used this at Troy, we figured out a particular individual we were actively investigating was living with his girlfriend for example. I was honestly amazed how densely filled in the map was of hits for a single plate based on the in-car cameras.)

You technically do not need to cache any data at all to accomplish this “flag a stolen vehicle” (or any other scenario where you are actively looking for a specific license plate). There are legitimate scenarios though where ALPR searches for recent data in a real time context can be very helpful.

One of the more common examples – someone robs a gas station, and they drove a vehicle. You don’t know the plate, but can look at the images that passed by the fixed location ALPRs in the time range, and then especially if you have a car description from the gas station attendant can figure out the plate associated with the vehicle.

To be clear I am not a lawyer, but in my opinion I think exigent circumstances make searching a few minutes of cached ALPR location data totally reasonable. In practice, New Hampshire’s 3 minute data retention is far too short. I could see arguments for several hours (imagine “I found a dead body on the side of the road”, that requires more time for it to be reported.) But we are meandering into the territory where it is not an active emergency “need to find someone who may have a gun and hurt people” that would justify those exigent circumstances. Those are the scenarios where getting a warrant is reasonable (no different than a geofence warrant if you do not have a plate and want to just search what cars passed by a camera within a certain date-time window, or no different than a CSLI warrant if you have an active suspect and want to search for a specific license plate).

Most states are retaining ALPR data for longer periods. While the Norfolk case was ongoing, Virginia set a standard across the state at 21 days. Before that it was up to the individual agency. It varies state by state, but states often mandate data retention around 30 days, or leave it up to the discretion of the police department.

Deleting Data does not prevent abuses

These data retention statutes are argued as a mechanism to prevent abuse. They do not accomplish this.

If you look through the cases in which officers abused the system to search for individuals, all of them searched for specific plates over-and-over again, sometimes hundreds of times.

If you retain data for 20 days, you can just go and do a search every 20 days, keep notes on the data as you so wish, and then do another search 20 days later. Getting rid of old data, in-and-of-itself, does nothing to prevent that abuse. In fact if someone is actively stalking a person, you would expect them to regularly do searches, seeing where their victim is going on a regular basis while they have access to the system.

Simultaneously, deleting data does prevent its legitimate use in long term law enforcement investigations. It is totally normal for a murder investigation to take more than 30 days to identify a suspect. Gosh, sure would be nice to be able to then query the ALPR data to show whether a person was in the vicinity of the murder. Simultaneously it could be used by the defense for exculpatory purposes (which assuredly would take longer than 30 days).

So folks advocating for deleting data as a mechanism to prevent abuse are making things worse. It does not prevent abuse, and limits the utility of ALPR for historical investigations. The only way data retention by itself prevents abuse is if you do not cache data at all (like in New Hampshire), and only use ALPRs for the active alert situation.

What Smart Regulation Looks Like

One of the reasons I say that the current standards to prevent abuse are laughable is that data retention policies and internal PD policies on when the data should be searched have been in place in most departments for years (if not a decade) at this point. The examples where searching ALPR data to stalk an intimate partner were obviously not prevented via data retention policies.

Alas, my suggestion that some data is cached for real time investigations (longer than 3 minutes), and that a warrant should be required outside of this window, does not prevent that type of abuse either. Most departments have in place reasons why a search can be conducted, and some states have specific statutes identifying impermissible reasons for conducting searches. In the Norfolk IJ case, officers, when entering a reason for a search (which was often omitted), sometimes supplied reasons that appeared prima facie illegal, such as “protest”.

Departments, even if they have a standard to do internal audits, often do not follow them. It took Tyler Dukes asking Raleigh PD for their audit results for them to even conduct their first audit.

This is a long standing problem for PDs, not just with ALPRs, but also with searching criminal history illegally. IJ collating a dozen cases of arrests of ALPR misuse across the country is not evidence these systems are working, as it is likely the case that only the most egregious abuses are ever caught.

In addition to creating state statutes to mandate that a warrant be used for historical ALPR searches, states should, at a minimum, have clear punishments for illegal searches. These should include at a minimum losing your job, and being banned from accessing the system forever. When I was a crime analyst in New York (and ditto for when I worked at DCJS), this was the standard for misusing the criminal history search database.

If there is a standard for just retaining active search data for less than 24 hours, it does present a potential simple check that should be flagged – if a specific plate or specific camera is searched twice within 2 days, it should be flagged to review more closely. Flock does have their own system to identify suspicious search history.

The bigger issue to me though is who is doing the reviewing. It does not make sense to put this on vendors, and PDs just have not seriously devoted resources to this, even in response to public criticism. This audit mechanism should be delegated to a third party, either a specific group in the state attorney general’s office, or a state criminal justice agency (like DCJS in New York).

So that of course needs to be explicitly set by state statute as well. Who is doing the auditing?

My focus so far has been on abuses via police departments themselves, but smart regulation should also specify auditing of the vendors themselves, as well as punishments if they fail to meet data standards. (I am not thinking so much TEMPEST attacks here, but more so “I left an unauthenticated endpoint willy nilly on the internet”.)

Indeed, many of the requirements I am suggesting are likely already on the books; the problem is that the entity responsible for auditing is often unspecified or lacks the resources to do the work. (Also it is often unclear what the punishments are for failing to abide by statutes. That also needs to be specifically stated.)

The Future

So while I hope (although I have no expectation) that my blog post can somehow influence current standards across the country, I think it is important to keep in mind surveillance not just as the world exists now, but how it may look in the foreseeable future.

I think states should just pull the band aid off and create statutes that require a warrant to search the historical ALPR data. (And this makes data sharing between agencies mostly moot, the real time searches only need to be done within your own jurisdiction.) Like I said at the beginning, the current case law on being able to reconstruct the whole of a person’s movements (which I think is quite reasonable) will eventually be met if the ALPR cameras become dense enough. So states can either create the statutes to dictate that a warrant is necessary themselves, or eventually have the court system thrust it upon them.

In a world filled with privately owned cameras in public spaces, I think these suggestions are still relevant. So similar to Carpenter for CSLI data, and Chatrie for geofence warrants, there should just be warrant standards for historically searching any surveillance footage. There need be no special distinction between ALPR data (public or private) or video cameras.

Even if the groups calling for the banning of Flock cameras get their way, this does not stop private owners from collecting the data. So banning Flock, by itself, does not prevent abuse of searching private cameras. Again I think it is better to just let the government retain the data (same as private vendors will retain the data), and have consistent warrant standards for police to obtain that historical data.

This, of course, is a burden to detectives. I believe that trade-off in protecting our personal liberties while still allowing police effective means to investigate cases is a reasonable one.


  1. There are some technicalities between whether just collecting the data is a search (which was the scenario in the Norfolk case) or whether doing an active search (e.g. an officer querying the system for license plate ABC1234). The Norfolk case was the former, but for this post I am focusing on officers actually searching the data (the latter scenario).↩︎

VerusCite: checking academic articles for hallucinations

I have a new app out, VerusCite. With the recent rise in popularity of GenAI tools like ChatGPT and Claude, this has also come along with academics writing slop articles.

One of the ways to check that slop is via looking at the articles citations. LLMs have some predictable failure modes in writing papers whole cloth – they tend to get details like complicated author lists wrong, or swap out incorrect journal titles. VerusCite is a tool for editors and reviewers to use to verify citations in a fast and cheap application.

It costs $2 to review a paper (and you get two free reviews on sign-up). If you want to see the output of a single example though, check out https://veruscite-data.com/share/E1-rn3TBwksENO_3hlmsRD0IG-EnXd6vfQg-upQZWQM

In addition to hallucinations, I have made many parts of the application just useful to editors in general. Many papers have minor errors in their bibliographies; typos, years off, author swaps, bad URLs, etc. Here is an example – no hallucinations that signal poor writing, but has seven different errors in the bibliography.

This is par for the course (it is quite possible 5% of citations have errors that look like this). The website has convenient tools to edit citations and export the fixed citations (whether minor errors or gross hallucinations) in various formats.

This makes much lighter work of the tedious job of formatting and checking citations for editors. One of the ways I think is critical to build generative AI tools is to consider the human in the loop from the start. My tool will ultimately make some errors (I error rate estimates in my public benchmark). I want it to be as fast for a human to confirm (or refute) the LLM label.

If you are an editor or a reviewer, I highly suggest you check the application out. Peer review journals (and pre-print servers that review the applications before posting), will need to use a tool like this as a first pass to ensure slop is not being posted.

AI writing is better than no writing

AI disclosure – this post was entirely written by myself.

I know AI writing is still pretty cringey – so I get that people are quite opposed to it. For people like me though (academics promoting their work, more technical oriented) I would like to proffer a slight defense of (even cringey) AI writing. Having an LLM tool help you write a blog post is better than not writing at all.

I have come to the personal opinion I just want you to disclose when you use AI. I am starting to get peer review requests for academic papers that are clearly LLM written, and they are not obviously worse than the typical (mostly horrid) way academics write papers (they may actually be better to be honest). Blog and social media posts I think are strictly worse to my personal tastes when using LLM writing (across many dimensions, for now anyway). But it is better to write something than nothing if you have something worth saying.

Where this matters for technical folks (and academics) is that your default SEO is awful. Most academic papers are behind paywalls. LLM research tools are not picking up peer reviewed papers. So if you have something worth saying, having LLMs write out a blog post for you is worth it relative to having no writing at all.

For examples of LLM writing I have on this site:

And then my book, Large Language Models for Mortals: A Practical Guide for Analysts with Python, is around 50% AI generated.

None of these examples I would have finished without the help of AI; either entirely writing for the example blog posts, or writing the first draft in the case of the LLM book. (The LLM book is good by the way, you would not be able to tell I generated that first draft at all with Claude.)

My suggestion is to not let AI entirely take the wheel, but to create a detailed outline and have the LLM review your prior writing. Those two things improve posts by a wide margin (in addition to making sure AI is not too verbose – keep those blog posts simple!). And then you still need to take the time to review your own writing (for references you need to check those for hallucinations).

To be clear again, AI writing is better than nothing if you have something actually useful to say to the world. The bigger issue with AI writing are slop merchants just wasting space. That happened before with LLM tools, it is just much easier and more prevalent now. Just own it when you use AI to help you write.

Notes on Valuing the Cost of Crime

AI disclosure – I used AI to write this blog post. I figure having an AI blog post is better than not writing it at all. I will always disclose though if I use AI to heavily write any content on this blog. (I use it for minor copy editing all the time.)

For the tech details, I used gemini flash 3.5 with medium reasoning in the Antigravity IDE, using the same advice I said in this blog post. (Minor preference to Claude Code for writing blog posts for those who care.) It is the outline of the thread I did on X (which I wrote entirely by hand). Using this approach, e.g. I give a detailed outline and prior examples, Pangram says this is only lightly AI assisted.

Notes on Valuing the Cost of Crime

We often hear eye-popping figures about the “cost of crime.” For example, that a single aggravated assault costs society $100,000, or that a statistical life is worth $10 million. But if you look under the hood of these estimates, they are built on a house of cards: Willingness-to-Pay (WTP) surveys.

WTP estimates wildly inflate the costs of crime. For realistic policy decisions and police budgeting, we should be using concrete measures that are easier to calculate and verify.

The Three Buckets of Crime Costs

To evaluate criminal justice interventions, we can break costs into three broad categories:

  • A) Cost to the individual: Personal hospital bills, lost work, and physical trauma.
  • B) Cost to public sector agencies: Police labor, court proceedings, jail/prison operations, and public healthcare programs like Medicaid.
  • C) Cost to society: Reduced business activity in high-crime areas and the loss of workers to the economy.

Most cost-of-crime estimates do not calculate these countable categories. Instead, they use survey estimates of willingness-to-pay to approximate the costs of crime to individuals. I believe WTP estimates themselves are junk and should not be used to guide operations.

The Scaling Problem of Willingness-to-Pay

If you have heard the phrase “a statistical life costs $10 million,” you are seeing a WTP estimate in action.

The scaling math is straightforward, but the resulting estimates themselves are junk. Researchers ask survey respondents questions like: “Would you pay $100 in increased taxes to fund sidewalk improvements that reduce pedestrian fatalities?” If the safety measures are estimated to reduce pedestrian deaths by 1 in 100,000 annually in a city, the math scales up simply:

100 × 100, 000 = $10, 000, 000

People are thus deemed “willing to pay” $10 million to reduce one death.

This methodology yields massive, noisy estimates. You can see these WTP metrics compiled on the RAND Cost of Crime site. The primary limitation is that survey respondents will agree to pay almost any seemingly small amount when they do not actually have to pay it. In one street lighting survey I reviewed, participants were paid $1 to participate and claimed they were willing to pay $200 on average for better streetlights. It is highly doubtful that someone who sells their time for $1 to complete a survey will actually pay $200 in taxes for streetlights. As Andrew Gelman has pointed out, valuing lives based on ability to pay reveals how detached these hypothetical exercises are from real-world resource constraints.

Countable Costs vs. Theoretical Valuations

When we rely on concrete cost estimates that can be verified—such as labor hours and medical bills—the figures are much lower.

For instance, while a WTP estimate for an aggravated assault is close to $100,000, Priscilla Hunt’s study on law enforcement costs estimates the actual police labor cost for an assault is closer to $10,000.

I cannot prove what people are hypothetically willing to pay. But I can show a police chief that reducing ten assaults in a specific sector will save $100,000 in labor and overtime.

This distinction matters for other public costs too. Serious physical assaults can easily generate six-figure medical bills. In New York, more than 70% of gun violence hospitalizations are paid for via Medicaid. While it is reasonable for state or federal governments to weigh these medical costs, a local county or police department does not bear them. It makes no sense for a local police department to justify its budget by claiming it is reducing Medicaid expenses.

Example Cost-Benefit Case Studies

When we restrict our analysis to tangible costs, how do common interventions stack up?

Hotspots Policing

Because crime is highly concentrated, we can identify specific geographic areas that generate massive public costs. I have previously written about locating Million-Dollar Hotspots in Baltimore and Dallas. In my research on redrawing hotspots, I show how spatial concentration makes 24/7 hotspots policing cost-effective based purely on offsetting tangible labor costs.

For code examples of this, check out my crimepy python library (DBSCAN with weights for cost of crime estimates).

ShotSpotter

I am much less bullish on acoustic gunshot detection systems like ShotSpotter due to their high cost, as detailed in my ShotSpotter cost-benefit analysis. I estimate that ShotSpotter saves approximately 1 life for every 100 shooting victims it covers by dispatching emergency services faster. If you value a life at $10 million using WTP, the system easily looks cost-effective. If you use tangible costs, the math changes. ShotSpotter has not shown consistent evidence that it increases case clearances or prevents victimization. In fact, saving a shooting victim via faster response generates higher medical bills than if they had died, highlighting the complex economics of reactive vs. proactive interventions.

Business Improvement Districts (BIDs)

A great example of societal cost-shifting is Business Improvement Districts (BIDs). As shown in John MacDonald and colleagues’ study on BIDs in Los Angeles, BIDs demonstrate that commercial businesses are actually willing to spend their own money to improve safety in their areas through private security, cleaning services, and physical improvements. This is not hypothetical willingness-to-pay; it is a real-world, out-of-pocket expenditure by local merchants who calculate that reducing crime is directly worth their private investment.

Gun Violence Interventions (READI)

When looking at community-based interventions, the cost-benefit models face a different hurdle. Monica Bhatt and her colleagues evaluated Chicago’s READI program in their study on predicting and preventing gun violence. They claim a massive benefit of around $180,000 per participant (translating to a 3:1 benefit-cost ratio).

However, this estimated benefit of $180,000 is derived by mixing up WTP estimates and lifetime projections of individual offending (specifically, the Cohen & Piquero lifecourse model). As I discussed in my analysis of limits on gun violence interventions, extrapolating high-risk youth crime savings over an entire lifecourse using inflated WTP values creates a benefit estimate that is completely detached from the immediate budget realities of local governments.

The Missing Metric: The Value of an Arrest

This brings us to a major gap in criminology: we do not have good estimates for what it is worth to clear a crime.

Because crime is highly concentrated among a small number of chronic offenders, an arrest is often worth more than preventing a single crime. Apprehending a chronic offender can prevent dozens of future offenses.

This is why tools like automated License Plate Readers (LPR) are interesting. As Ozer’s study on LPR effectiveness shows, they are much cheaper than ShotSpotter and are highly cost-effective even if they only generate a small percentage increase in arrests. However, to truly calculate their ROI, we need a better grasp on the actual monetary value of a clearance.

To build better policy, we need to stop relying on WTP surveys and start measuring the real, tangible savings that police departments and local governments can actually bank.

References

  • Bhatt, M. P., Heller, S. B., et al. (2024). Predicting and preventing gun violence: An experimental evaluation of READI Chicago. The Quarterly Journal of Economics, 139(1), 1-56.

  • Cohen, M. A., & Piquero, A. R. (2009). New evidence on the monetary value of saving a high risk youth. Journal of Quantitative Criminology, 25(1), 25-49.

  • Hunt, P., Saunders, J., & Kilmer, B. (2019). Estimates of law enforcement costs by crime type for benefit-cost analyses. Journal of Benefit-Cost Analysis, 10(1), 95-123.

  • MacDonald, J., Golinelli, D., Stokes, R. J., & Bluthenthal, R. (2010). The effect of business improvement districts on the incidence of violent crimes. Injury Prevention, 16(5), 327-332.

  • Ozer, M. (2016). The impact of automatic number plate recognition (ANPR) technology on crime. Police Journal, 89(2), 117-132.

  • Wheeler, A. P., & Reuter, S. (2021). Redrawing Hot Spots of Crime in Dallas, Texas. Police Quarterly, 24(2), 159-184.

Gathering interest in tech courses

Quick post this morning — I have a survey up gathering input on interest in short, technical courses.

Think 2-3 days, potentially in person/synchronous.

If you have taken a course with Paul Allison at Horizon’s, or an ICPSR summer course, those are similar examples. But, the main difference will be these courses are to prepare you for pursuing private sector roles.

These will be aimed at:

  • grad level social science students
  • current professors looking to pursue private sector roles
  • current data analysts looking to get into data science
  • undergrads with some more technical background

Survey lists potential courses (python for data analysis, intro to LLM APIs, SQL + Dashboards, using agent based tools for analysis), the course medium (in person vs video), price points.

If you are a university or organization interested in hosting such sessions for your students, let me know as well. Happy to chat to you about bringing this to your campus.