Crime De-Coder LLC Website

So I have created CRIME De-Coder LLC, a firm to do my consulting work with police departments. Check out my website, crimede-coder.com.

Feedback is welcome. In particular check out the services pages, and my first blog post on what distinguishes my services from most firms. Providing computer code to generate the end product is “teaching a man a fish”, whereas most firms just drop a final report and leave.

And of course feel free to reach out to consult@crimede-coder.com if you are interested in pursuing a project. Going forward I plan on making a new post around once a month, so sign up in your feed reader or using a service like IFTTT.


Setting up a stand alone website is not that hard in the end. Currently it is a static site with some custom javascript (hosted on Hostinger). I should do a PHP server for the new blog posts and RSS feed eventually, but for now this is fine. I suggest for those interested in the same get the Jon Duckett books (HTML/Javascript/PHP) for overview of the tech, and then check out Dani Kross’s youtube tutorials (for random things like editing the htaccess file).

I am not doing a newsletter for the blog-posts, as I am concerned it will get my email on random block lists. But if there is demand for it in the future I will figure out some other service I guess to do that.

I wanted a more bare-metal setup (not a hosted wordpress like this site), as in the future I will likely do demo’s of dashboards, host some pyscript, make a sign in for paid content, etc. I just wanted flexibility from the start. So stay tuned for more content from CRIME De-Coder!

Scorpion was probably not doing hot spots policing

So the Wall Street Journal had a recent article describing how crackdowns in hot spots of crime may not be the best policing tactic, Tyre Nichols Case Prompts Questions About Police Tactics in Crime Hot Spots. This is actually an OK article, but to be clear “hot spots” policing isn’t really defined by police tactics, hot spots are just a method to identify small areas with the most crime in a city. Identifying the hot spots does not explicitly determine the policing (or non-policing) tactic that one should use to reduce crime in that area. The Washington Post had a recent article in a similar vein critiquing the work of Tamara Herold in Breonna Taylor’s death. The WaPo article even prompted a response by a group of well known criminologists how it was inappropriate to blame Herold’s strategy.

So hotspots have always had a mix of different policing tactics that go with it, the most common strategies I would say are problem oriented policing (Braga et al., 1999), increased street or traffic stops (MacDonald et al., 2016; Sherman & Rogan, 1995), or simply patrolling/hanging out in the area (Groff et al., 2015; Koper, 1995). The WSJ article talks about Joel Caplan’s RTM group (which I think do good work), and they are really just doing a version of problem oriented policing. (POP has always had a component of working in tandem with the community and different public/private sector agencies.)

One of the reasons I wanted to write about this post though, is that often in my career I see a disconnect in purportedly hot spots policing (or similar tactics, such as DDACTS) on paper and what is actually happening on the ground. So using the Memphis Open Crime Data, I identified the top 100 street segments in terms of violent crime (code on github to replicate). As I suspected, the place where Nichols was pulled over is not a hot spot of crime, making the connection between the Scorpion units behavior and hot spots policing tactics a bit suspect.

If the embedded google map does now work, here is a screen shot to show how none of the top 100 street midpoints are around the location of where Nichol’s was initially stopped:

It happens to be the case that officers often have misperceptions of where hot spots are (Macbeth & Ariel, 2019; Ratcliffe & McCullagh, 2001). And that if left to no oversight, there tends to be a mismatch between where police proactivity is occurring and where the most serious crime is spatially concentrated (Wheeler et al., 2018). That is why a system to feed back information to officers for whether they are making high quality stops is so important (Worden et al., 2018).

To be clear, this is not me making excuses for researchers or crime analysts to not know what is actually occurring in their jurisdictions, and to potentially ignore the secondary harms that can come with intensive policing. But in my experience, taking the time to do hot spots policing right, which at its most basic is actually identifying hot spots using data, is a good sign that police departments take seriously the tactics they use and to seriously think about mitigating some of these secondary harms. Hot spots policing does not intrinsically result in unequal outcomes, which can be done via tactics that mitigate harm (such as problem oriented policing), or constructing a hot spots policy that promotes racial equity in outcomes from the start (Wheeler, 2020).

References

  • Braga, A.A., Weisburd, D.L., Waring, E.J., Mazerolle, L.G., Spelman, W., & Gajewski, F. (1999). Problem‐oriented policing in violent crime places: A randomized controlled experiment. Criminology, 37(3), 541-580.
  • Groff, E. R., Ratcliffe, J. H., Haberman, C. P., Sorg, E. T., Joyce, N. M., & Taylor, R. B. (2015). Does what police do at hot spots matter? The Philadelphia policing tactics experiment. Criminology, 53(1), 23-53.
  • Koper, C.S. (1995). Just enough police presence: Reducing crime and disorderly behavior by optimizing patrol time in crime hot spots. Justice Quarterly, 12(4), 649-672.
  • Macbeth, E., & Ariel, B. (2019). Place-based statistical versus clinical predictions of crime hot spots and harm locations in Northern Ireland. Justice Quarterly, 36(1), 93-126.
  • MacDonald, J., Fagan, J., & Geller, A. (2016). The effects of local police surges on crime and arrests in New York City. PLoS one, 11(6), e0157223.
  • Ratcliffe, J.H., & McCullagh, M.J. (2001). Chasing ghosts? Police perception of high crime areas. British Journal of Criminology, 41(2), 330-341.
  • Sherman, L.W., & Rogan, D.P. (1995). Effects of gun seizures on gun violence:“Hot spots” patrol in Kansas City. Justice Quarterly, 12(4), 673-693.
  • Wheeler, A.P. (2020). Allocating police resources while limiting racial inequality. Justice Quarterly, 37(5), 842-868.
  • Wheeler, A. P., Steenbeek, W., & Andresen, M. A. (2018). Testing for similarity in area‐based spatial patterns: Alternative methods to Andresen’s spatial point pattern test. Transactions in GIS, 22(3), 760-774.
  • Worden, R.E., McLean, S.J., Wheeler, A.P., Reynolds, D.L., Dole, C., Cochran, H. Smart Stops: An Inquiry into Proactive Policing. Summary Report to the National Institute of Justice, Award No. 2013-MU-CX-0012.

ptools R package update

So as an update to my R package ptools, I have bumped a major version change to 2.0, which is now up on CRAN.

There is no new functionality, but I wanted to bump versions because I swapped out using rgdal/rgeos with sf (rgdal and rgeos are being deprecated). All the functions currently still take as inputs/output sp objects. If I ever get around to it, I will convert the functions to take either. They are somewhat inefficient with conversions, but if you are doing something where it matters you should likely switch data-engineering to another system entirely (such as via SQL in postgis directly). Generating hexagons should actually be faster now, as the sf version I swapped out is vectorized (whereas how I was using sp prior was a loop).

I debate every now and then just letting this go. I can see on cranlogs I have a total of just over 1k (as of 2/7/2023) downloads, and averaged 200 some last month (grand total, last month).

Time is finite, so I have debated on dropping this and just porting most of the functions over into python. Those cumulative downloads are partially bots (I may have racked up 100 of those downloads in my CICD actions). Let me know if you actually use this, as that gives me feedback whether to bother continuing to develop/update this.

Preprint: Analysis of LED street light conversions on firearm crimes in Dallas, Texas

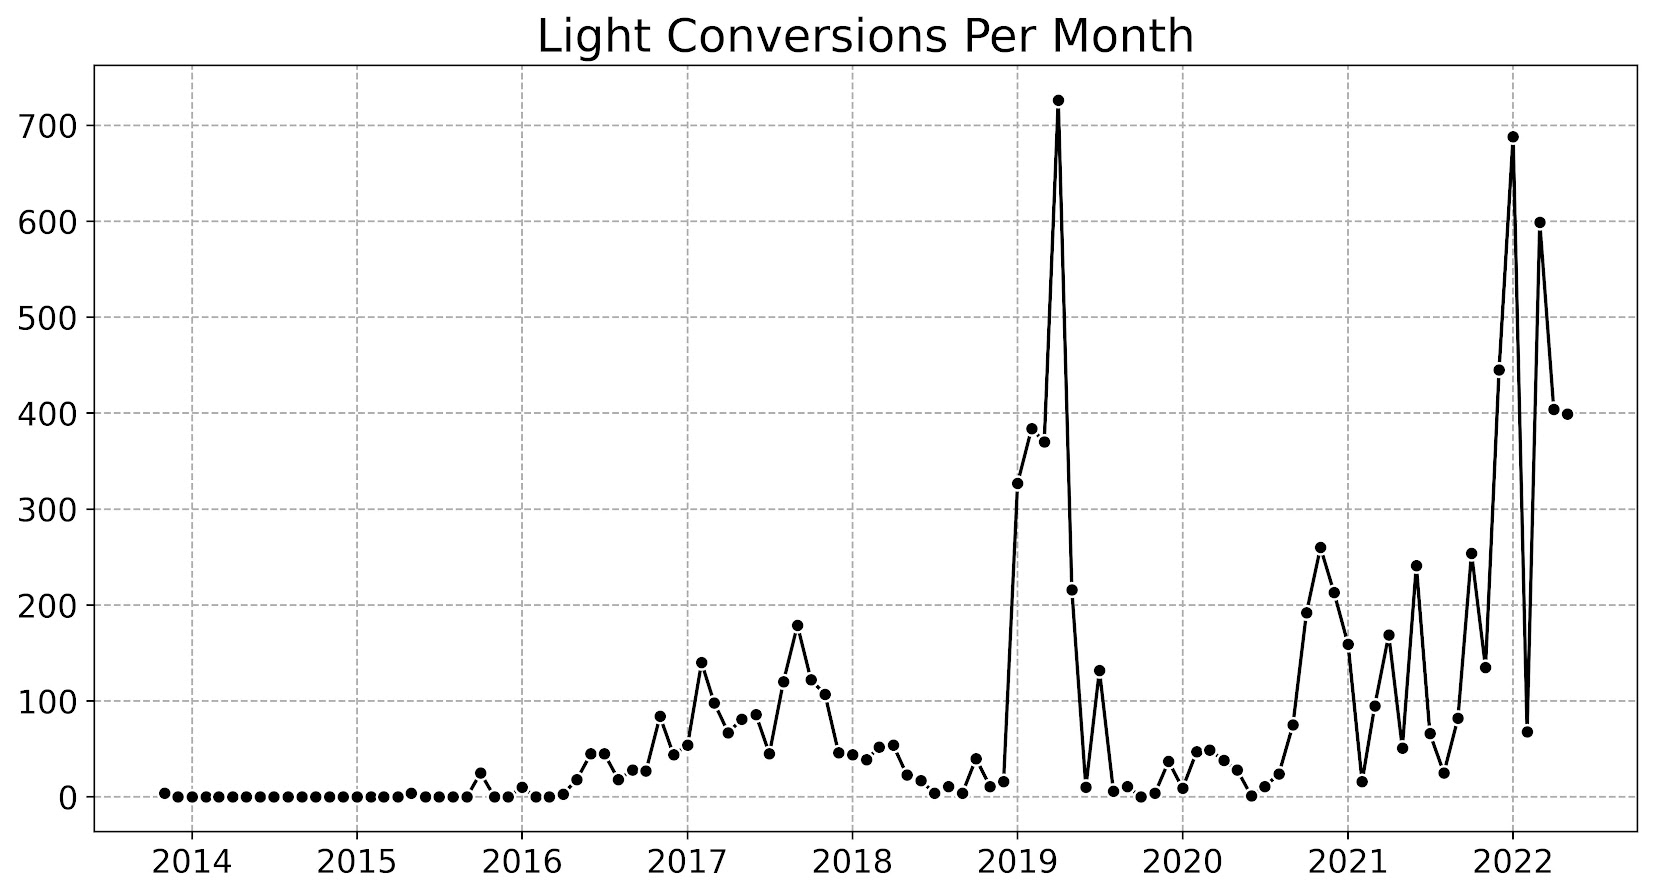
I have a new pre-print out, Analysis of LED street light conversions on firearm crimes in Dallas, Texas. This work was conducted in collaboration with the Child Poverty Action Lab, in reference to the Dallas Taskforce report. Instead of installing the new lights though at hotspots that CPAL suggested, Dallas stepped up conversion of street lamps to LED. Here is the temporal number of conversions over time:

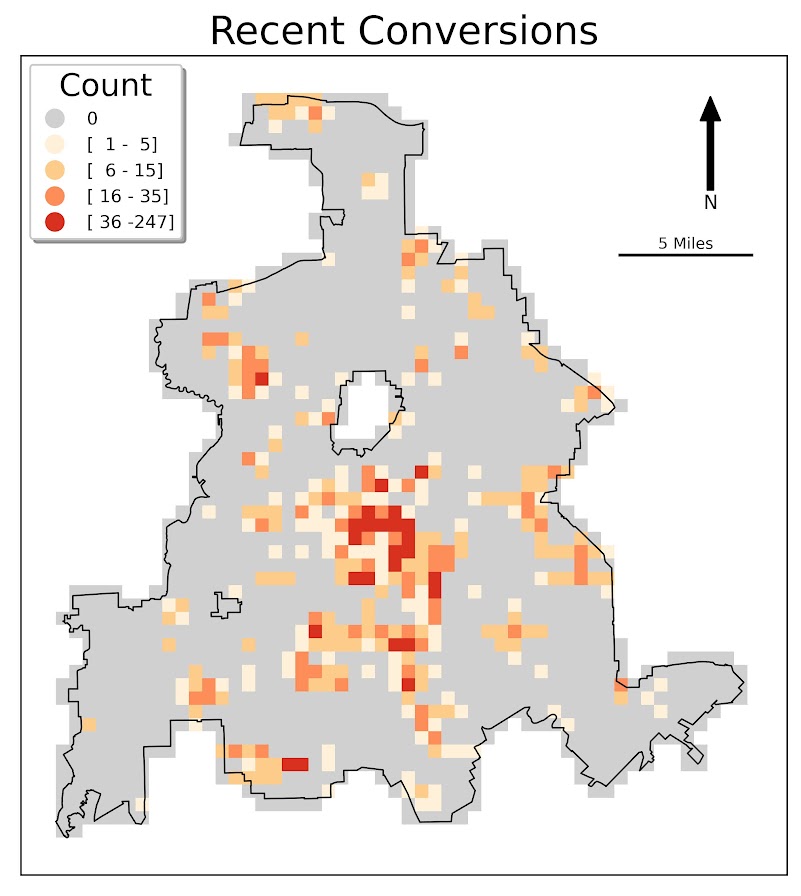
And here is an aggregated quadrat map at quarter square mile grid cells (of the total number of LED conversions):

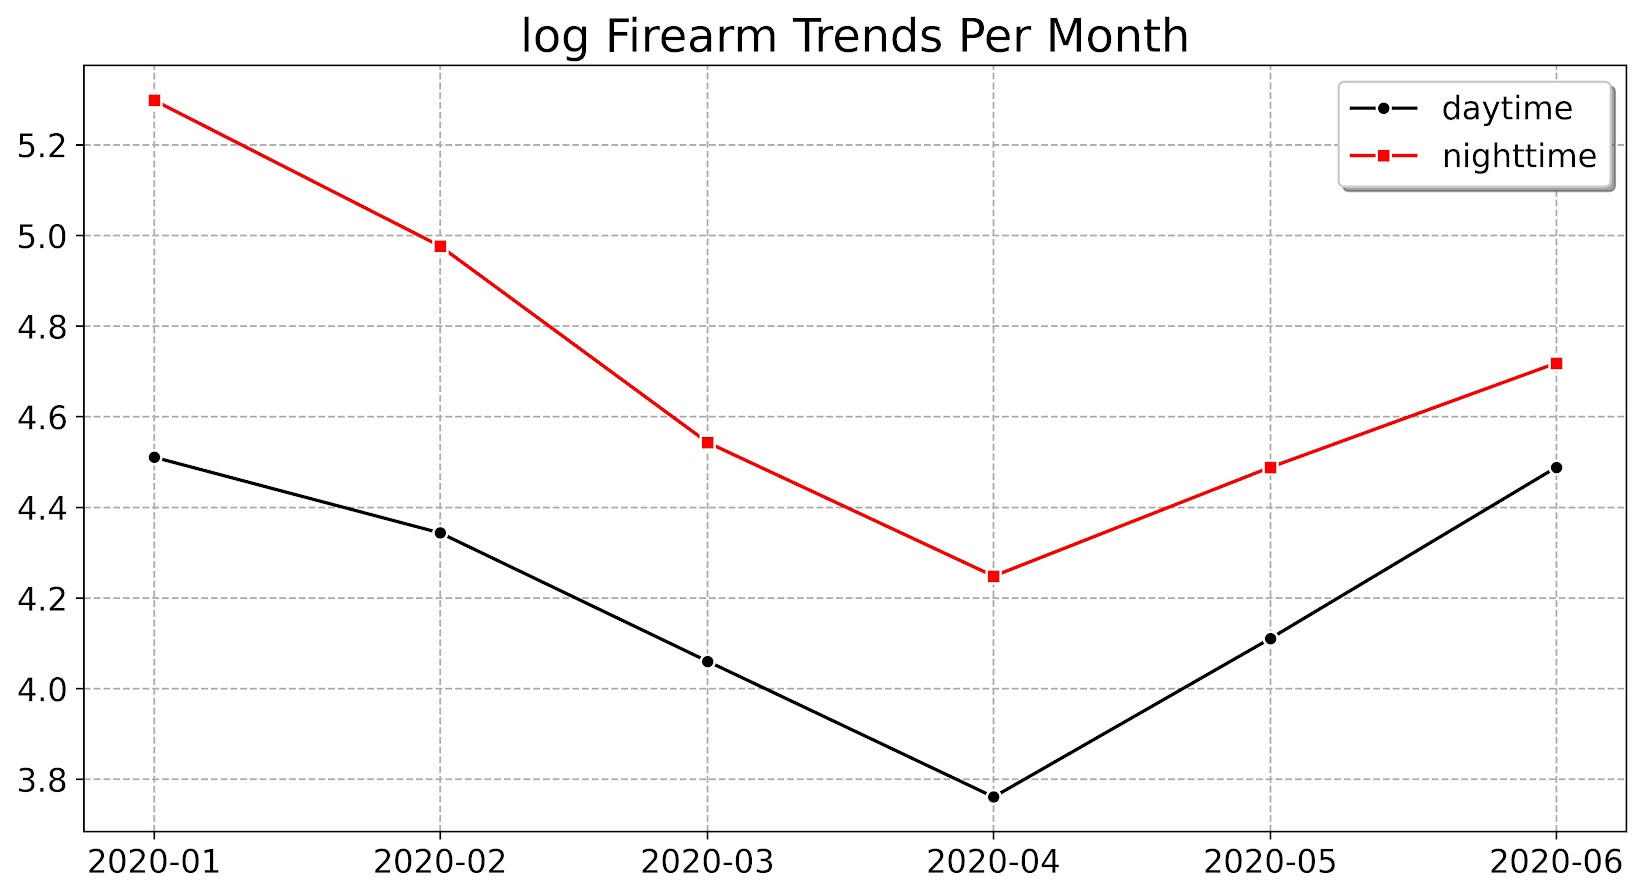
I use a diff-in-diff design (compare firearm crimes in daytime vs nighttime) to test whether the cumulative LED conversions led to reduced firearm crimes at nighttime. Overall I don’t find any compelling evidence that firearm crimes were reduced post LED installs (for a single effect or looking at spatial heterogeneity). This graph shows in the aggregate the DiD parallel trends assumption holds citywide (on the log scale), but the identification strategy really relies on the DiD assumption within each grid cell (any good advice for graphically showing that with noisy low count data for many units I am all ears!).

For now just wanted to share the pre-print. To publish in peer-review I would need to do a bunch more work to get the lit review where most CJ reviewers would want it. Also want to work on spatial covariance adjustments (similar to here, but for GLM models). Have some R code started for that, but needs much more work/testing before ready for primetime. (Although as I say in the pre-print, these should just make standard errors larger, they won’t impact the point estimates.)

So no guarantees that will be done in anytime in the near future. But no reason to not share the pre-print in the meantime.

Hot spots of crime in Raleigh and home buying

So my realtor, Ellen Pitts (who is highly recommended, helped us a ton remotely moving into Raleigh), has a YouTube channel where she talks about real estate trends. Her most recent video she discussed a bit about crime in Raleigh relative to other cities because of the most recent shooting.

My criminologist hot take is that generally most cities in the US are relatively low crime. So Ellen shows Dallas has quite a few more per-capita shootings than Raleigh, but Dallas is quite safe “overall”. Probably somewhat contra to what most people think, the cities that in my opinion really have the most crime problems tend to be smaller rust belt cities. I love Troy, NY (where I was a crime analyst for a few years), but Troy is quite a bit rougher around the edges than Raleigh or Dallas.

So this post is more about, you have already chosen to move to Raleigh – if I am comparing house 1 and house 2 (or looking at general neighborhoods), do I need to worry about crime in this specific location?

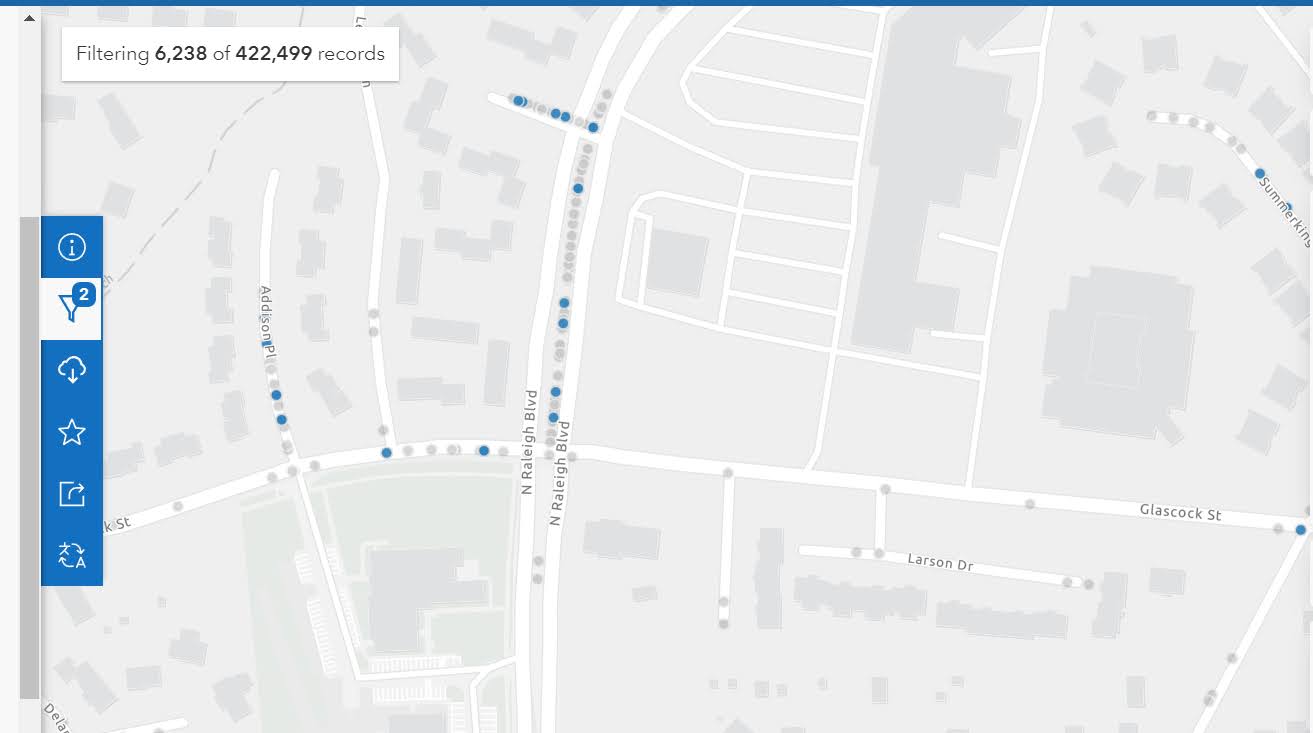
So for a few specific resources/strategies for the home hunter. Not just in Raleigh, but many cities now have an open data portal. You can often look at crime. Here is an example with the Raleigh open data:

So if you have a specific address in mind, you can go and see the recent crime around that location (cities often fuzz the address a bit, so the actual points are just nearby on that block of the street). Blue dots in that screenshot are recent crimes in 2022 against people (you can click on each dot and get a more specific breakdown). Be prepared when you do this – crime is everywhere. But that said the vast majority of minor crime incidents should not deter you from buying a house or renting at a particular location.

Note I recommend looking at actual crime data (points on a map) for this. Several vendors release crime stats aggregated to neighborhoods or zipcodes, but these are of very low quality. (Often they “make up” data when it doesn’t exist, and when data does exist they don’t have a real great way to rank areas of low or high crime.)

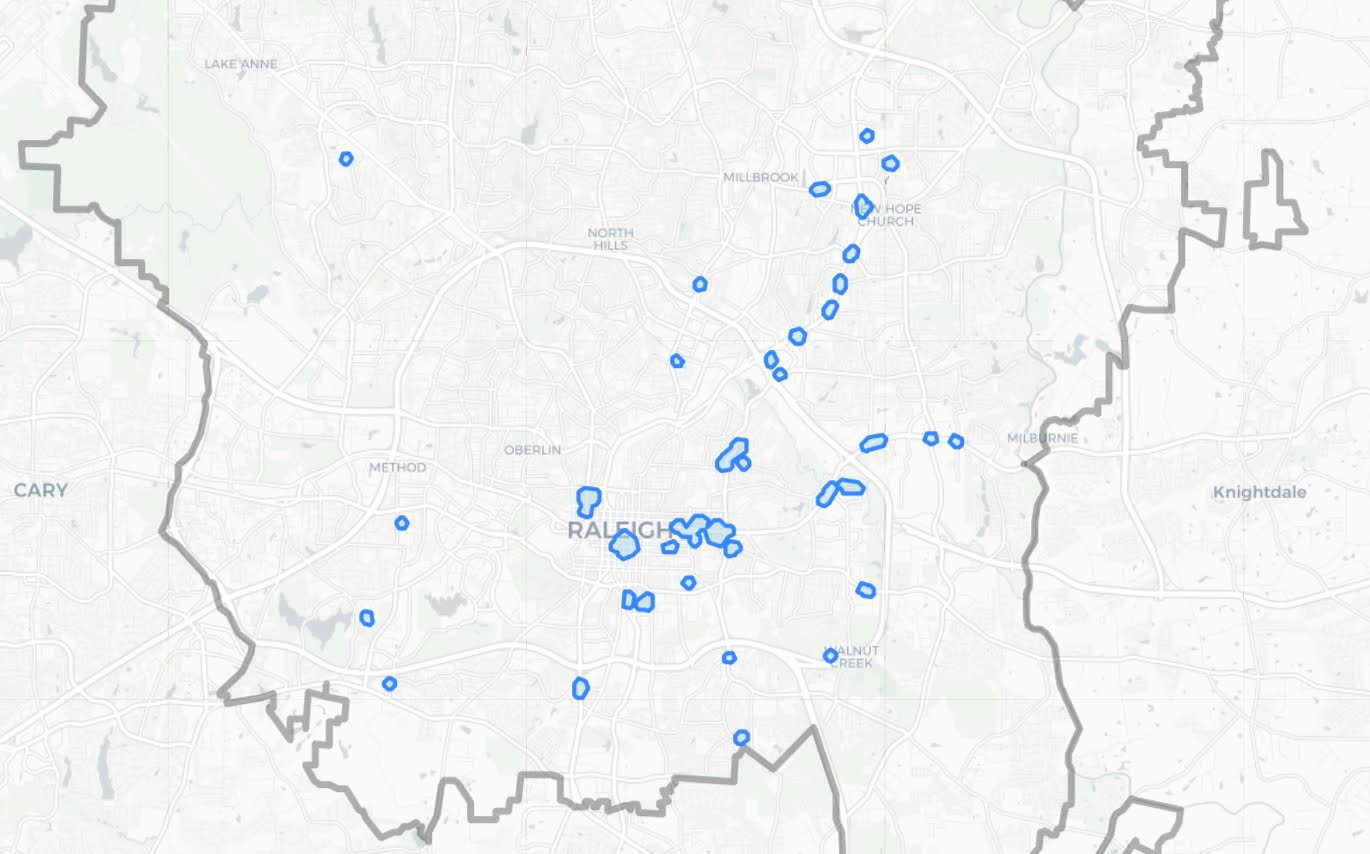
For the more high level, should I worry about this neighborhood, I made an interactive hotspot map.

For the methodology, I focused on crimes that I would personally be concerned with as a homeowner. If I pull larceny crimes, I am sure the Target in North Hills would be a hotspot (but I would totally buy a condo in North Hills). So this pulls the recent crime data from Raleigh open data starting in 2020, but scoops up aggravated assaults, interpersonal robberies, weapon violations, and residential burglaries. Folks may be concerned about drug incidents and breaking into cars as well, but my experience those also do not tend to be in residential areas. The python code to replicate the map is here.

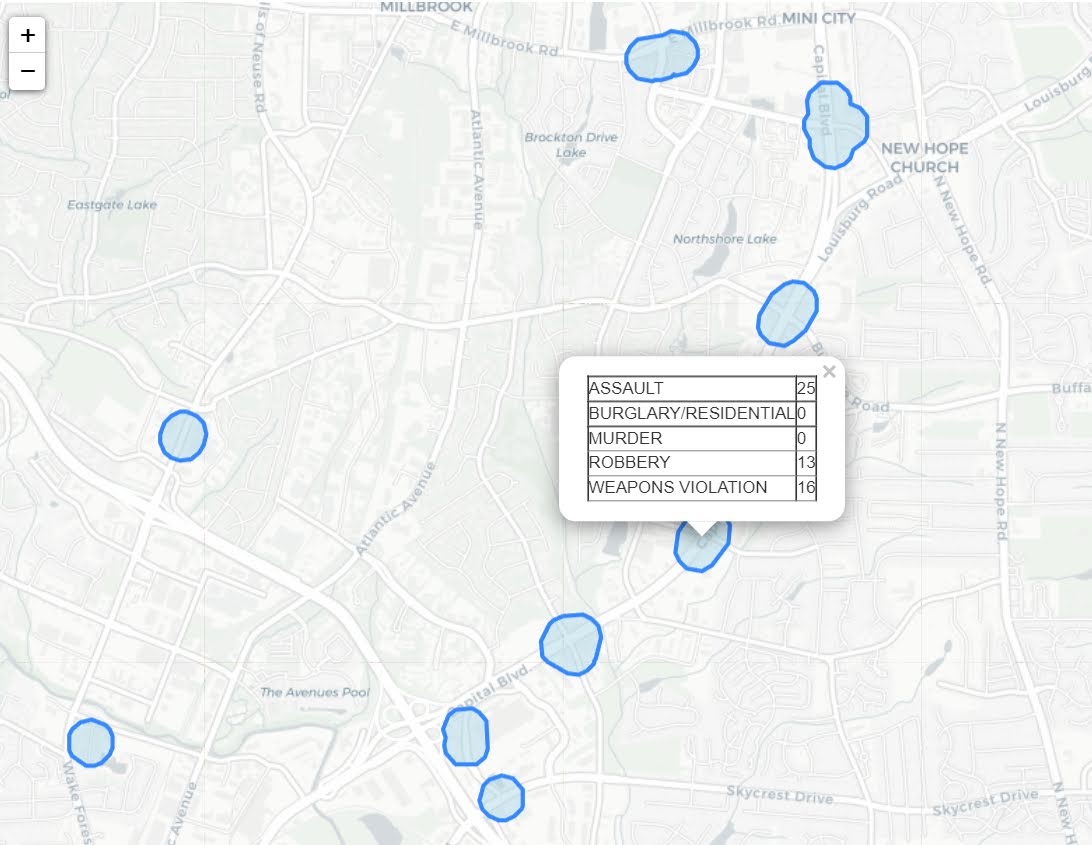
Then I created DBScan clusters that had at least 34 crimes – so these areas average at least one of these crimes per month over the time period I sampled. Zooming in, even though I tried to filter for more potentially residential related crimes, you can see the majority of these hot spots of crime are commercial areas in Raleigh. So for example you can zoom in and check out the string of hot spots on Capital Blvd (and if you click a hot spot you can get breakdowns of specific crime stats I looked at):

Very few of these hot spots are in residential neighborhoods – most are in more commercial areas. So when considering looking at homes in Raleigh, there are very few spots I would worry about crime at all in the city when making a housing choice. If moving into a neighborhood with a higher proportion of renters I think is potentially more important long term signal than crime here in Raleigh.

Home buying and collective efficacy

With the recent large appreciation in home values, around 20% in the prior year, there have been an increase in private investors purchasing homes to rent out. Recent stories on this by Tyler Dukes and colleagues have collated open parcel data to identify the scope of these companies across all of North Carolina.

For bit of background, I tried to purchase a home in Plano, TX early 2018. Homes in our price range at that time were going in a single day and typically a few thousand over asking price.

Fast forward to early 2021, I am full remote data scientist instead of a professor, and kiddo is in online school. Even with the pay bump, housing competition was even worse in Plano at this point, so we knew we were likely going to have to move school districts to be able to purchase a home. So we decided to strike out, and ended up looking around Raleigh. Ended up quite quickly deciding to purchase a new build home in the suburb of Clayton (totally recommend our realtor, Ellen Pitts, her crew did quite a bit of work for us remotely).

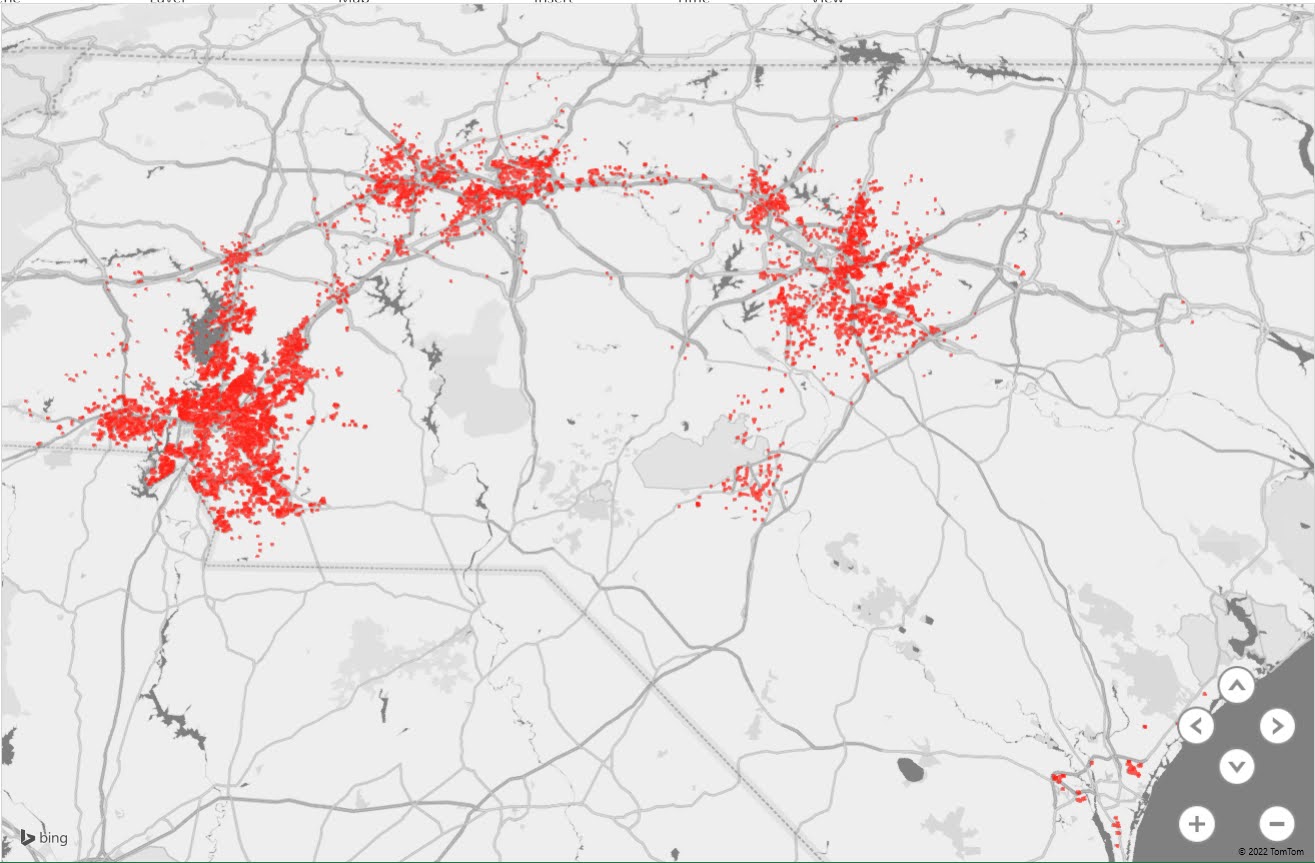
I was lucky to get in then it appears – many of the new developments in the area are being heavily scooped up by these equity firms (and rent would be ~$600 more for my home than the mortgage). So I downloaded the public data Dukes put together, and loaded it into Excel to make a quick map of the properties.

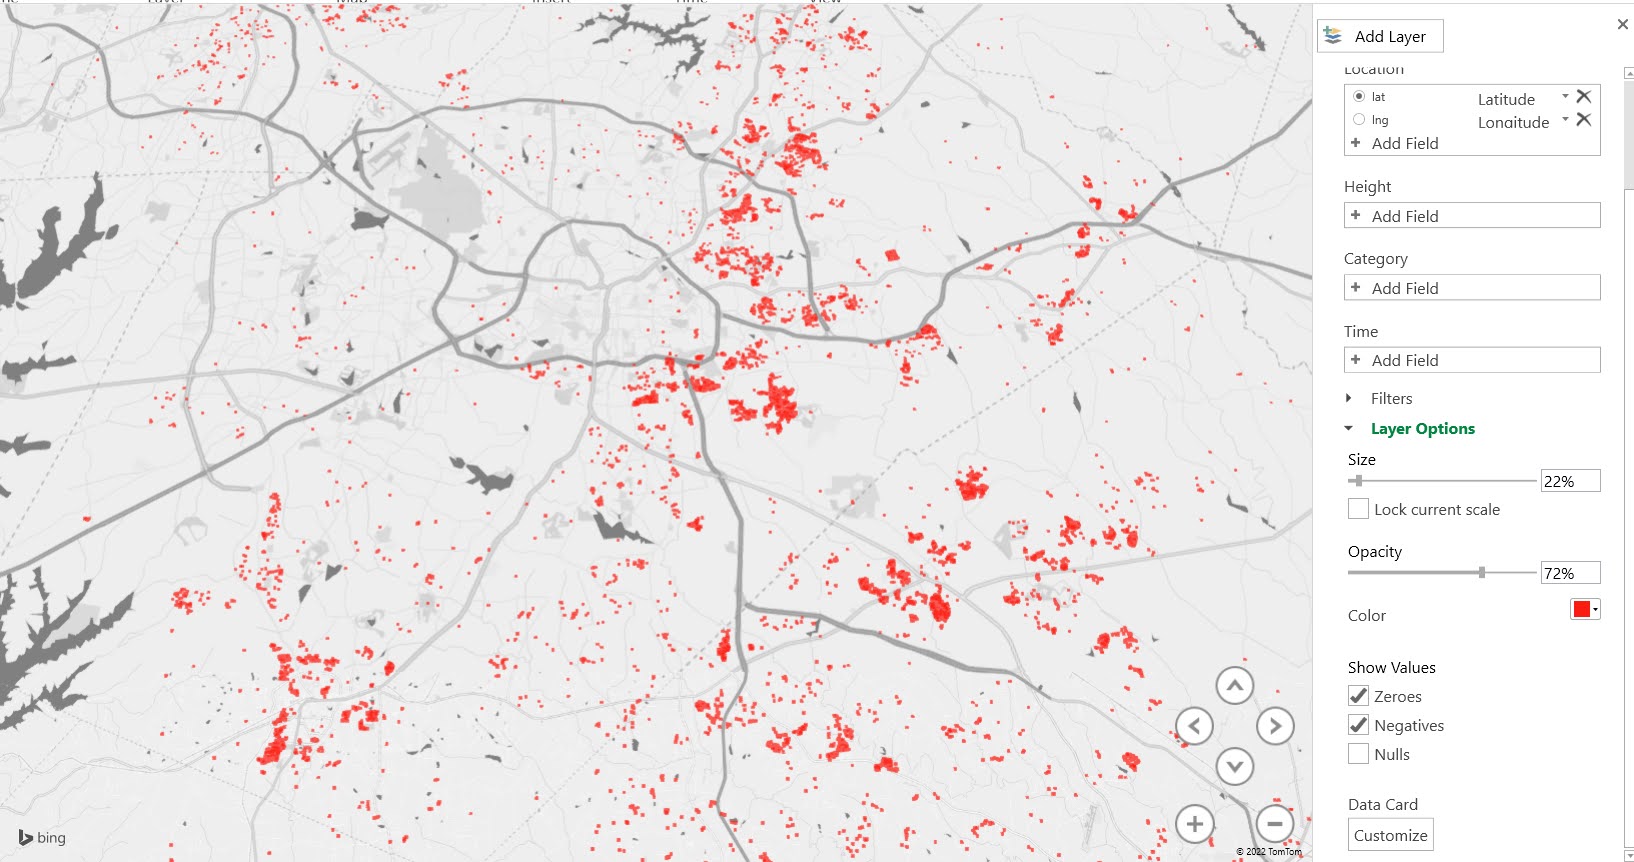
For a NC state view, we have big clusters in Charlotte, Greensboro and Raleigh:

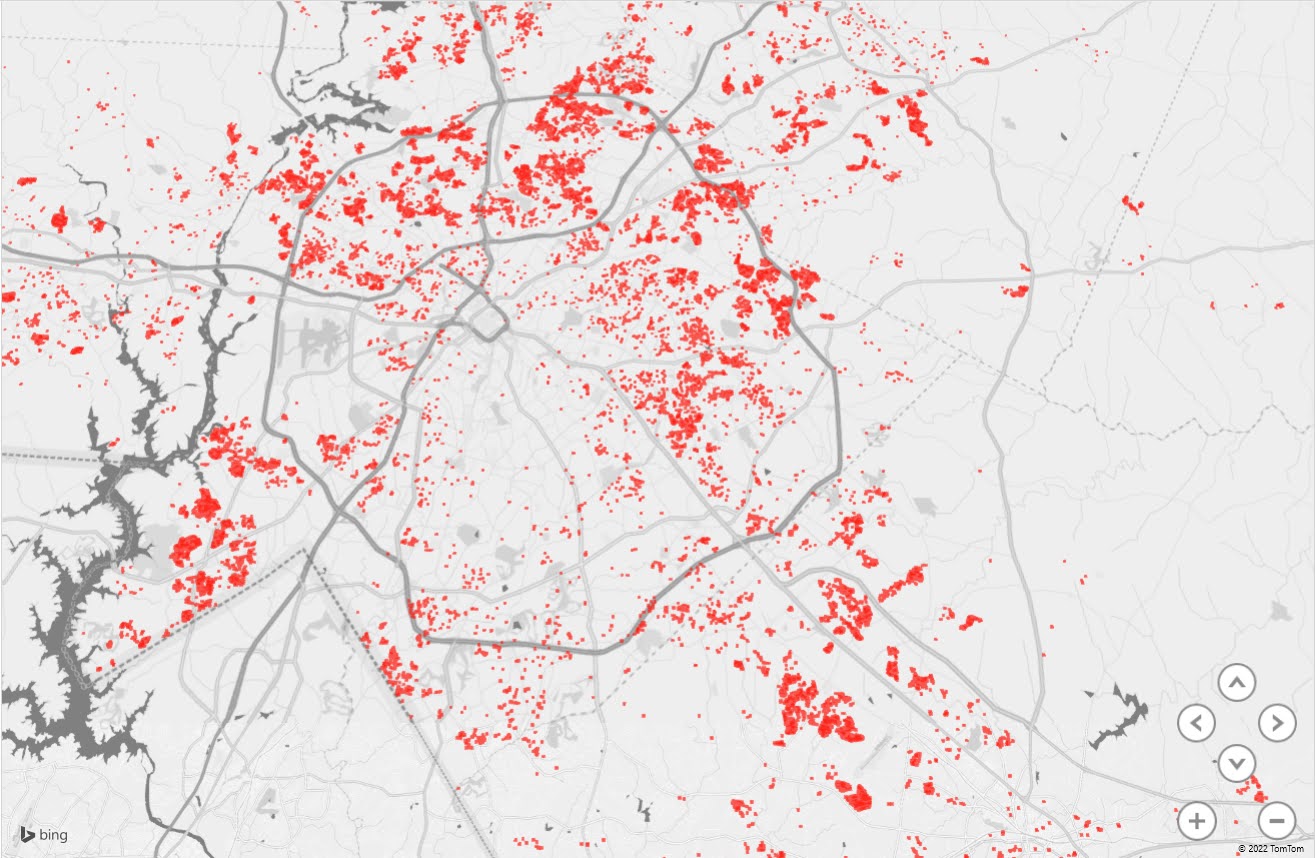
We can zoom in, and here is an overview of triangle area:

So you can see that inside the loop in Raleigh is pretty sparse, but many of the newer developments on the east side have many more of the private firm purchased houses. Charlotte is much more infilled with these private firms purchasing properties.

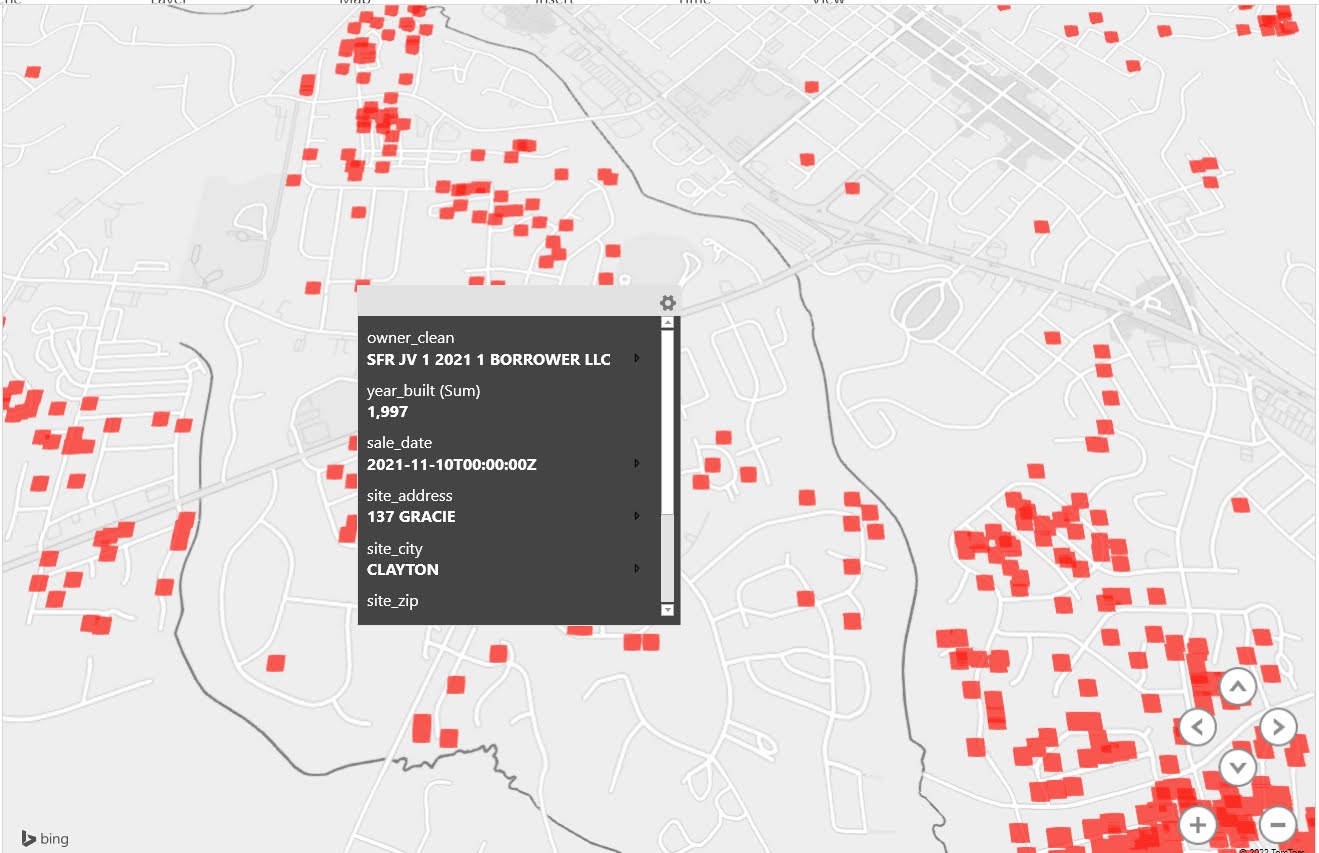
Zooming in even further to my town of Clayton, there is quite a bit of variance in the proportion of private vs residential purchases across various developments. My development is less than 50% of these purchases, several developments though appear almost 100% private purchased though. (This is not my home/neighborhood FYI.)


So what does this have to do with collective efficacy? Traditionally areas with higher home ownership have been associated with lower rates of crime. For not criminologists reading my blog, one of the most prominent criminological theories is that state actions only move the needle slightly on increasing/decreasing crime, people enforcing social norms is a bigger factor that explains high crime vs low crime areas. Places with people churning out more frequently – which occurs in areas with more renters – tend to have fewer people effectively keeping the peace. Because social scientists love to make up words, we call this concept collective efficacy.

Downloading and looking at this data, while I was mostly just interested in zooming into my neighborhood and seeing the infill of renters, sparked a criminological hypothesis: I expect neighborhoods with higher rates of private equity purchased housing in the long run to have higher rates of criminal behavior.

This hypothesis will be difficult to test in the wild. It is partially confounded with capital – those who buy their homes accumulate more wealth over time (again mortgage is quite a bit cheaper than rent, so even ignoring home value appreciation this is true). But the variance in the number of homes purchased by private equity firms in different areas makes me wonder if there is enough variation to do a reasonable research design to test my hypothesis, especially in the Charlotte area in say two or three years post a development being finished.

Downloading Social Vulnerability Index data

So Gainwell has let me open source one of the projects I have been working on at work – a python package to download SVI data. The SVI is an index created by the CDC to identify areas of high health risk in four domains based on census data (from the American Community Survey).
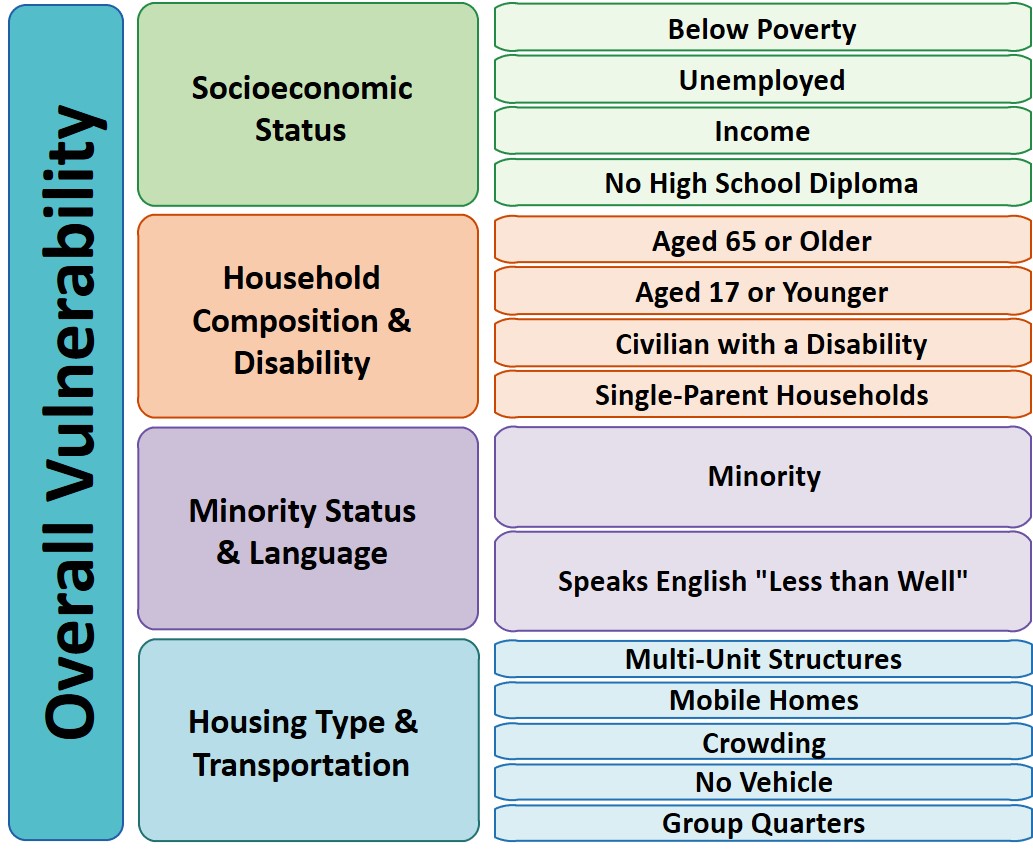
For my criminologist friends, these are very similar variables we typically use to measure social disorganization (see Wheeler et al., 2018 for one example criminology use case). It is a simple python install, pip install svi-data. And then you can get to work. Here is a simple example downloading zip code data for the entire US.

import numpy as np
import pandas as pd
import svi_data

# Need to sign up for your own key
key = svi_data.get_key('census_api.txt')

# Download the data from census API
svi_zips = svi_data.get_svi(key,'zip',2019)
svi_zips['zipcode'] = svi_zips['GEO_ID'].str[-5:]

Note I deviate from the CDC definition in a few ways. One is that when I create the themes, instead of using percentile rankings, I z-score the variables instead. It will likely result in very similar correlations, but this is somewhat more generalizable across different samples. (I also change the denominator for single parent heads of households to number of families instead of number of households, I think that is likely just an error on CDC’s part.)

Summed Index vs PCA

So here quick, lets check out my z-score approach versus a factor analytic approach via PCA. Here I just focus on the poverty theme:

pov_vars = ['EP_POV','EP_UNEMP','EP_PCI','EP_NOHSDP','RPL_THEME1']
svi_pov = svi_zips[['zipcode'] + pov_vars ].copy()

from sklearn import decomposition
from sklearn.preprocessing import scale

svi_pov.corr()

Note the per capita income has a negative correlation, but you can see the index works as expected – lower correlations for each individual item, but fairly high correlation with the summed index.

Lets see what the index would look like if we used PCA instead:

pca = decomposition.PCA()
sd = scale(svi_pov[pov_vars[:-1]])
pc = pca.fit_transform(sd)
svi_pov['PC1'] = pc[:,0]
svi_pov.corr() #almost perfect correlation

You can see that besides the negative value, we have an almost perfect correlation between the first principal component vs the simpler sum score.

One benefit of PCA though is a bit more of a structured approach to understand the resulting indices. So we can see via the Eigen values that the first PC only explains about 50% of the variance.

print(pca.explained_variance_ratio_)

And if we look at the loadings, we can see a more complicated pattern of residual loadings for each sucessive factor.

comps = pca.components_.T
cols = ['PC' + str(i+1) for i in range(comps.shape[0])]
load_dat = pd.DataFrame(comps,columns=cols,index=pov_vars[:-1])
print(load_dat)

So for PC3 for example, it has areas with high no highschool, as well as high per capita income. So higher level components can potentially identify more weird scenarios, which healthcare providers probably don’t care about so much by is a useful thing to know for exploratory data analysis.

Mapping

Since these are via census geographies, we can of course map them. (Here I grab zipcodes, but the code can download counties or census tracts as well.)

We can download the census geo data directly into geopandas dataframe. Here I download the zip code tabulation areas, grab the outline of Raleigh, and then only plot zips that intersect with Raleigh.

import geopandas as gpd
import matplotlib.pyplot as plt

# Getting the spatial zipcode tabulation areas
zip_url = r'https://www2.census.gov/geo/tiger/TIGER2019/ZCTA5/tl_2019_us_zcta510.zip'
zip_geo = gpd.read_file(zip_url)
zip_geo.rename(columns={'GEOID10':'zipcode'},inplace=True)

# Merging in the SVI data
zg = zip_geo.merge(svi_pov,on='zipcode')

# Getting outline for Raleigh
ncp_url = r'https://www2.census.gov/geo/tiger/TIGER2019/PLACE/tl_2019_37_place.zip'
ncp_geo = gpd.read_file(ncp_url)
ral = ncp_geo[ncp_geo['NAME'] == 'Raleigh'].copy()
ral_proj = 'EPSG:2278'
ral_bord = ral.to_crs(ral_proj)

ral_zips = gpd.sjoin(zg,ral,how='left')
ral_zips = ral_zips[~ral_zips['index_right'].isna()].copy()
ral_zipprof = ral_zips.to_crs(ral_proj)

# Making a nice geopandas static map, zoomed into Raleigh

fig, ax = plt.subplots(figsize=(6,6), dpi=100)

# Raleighs boundary is crazy
#ral_bord.boundary.plot(color='k', linewidth=1, edgecolor='k', ax=ax, label='Raleigh')
ral_zipprof.plot(column='RPL_THEME1', cmap='PRGn',
                 legend=True,
                 edgecolor='grey',
                 ax=ax)

# via https://stackoverflow.com/a/42214156/604456
ral_zipprof.apply(lambda x: ax.annotate(text=x['zipcode'], xy=x.geometry.centroid.coords[0], ha='center'), axis=1)

ax.get_xaxis().set_ticks([])
ax.get_yaxis().set_ticks([])

plt.show()

I prefer to use smaller geographies when possible, so I think zipcodes are about the largest areas that are reasonable to use this for (although I do have the ability to download this for counties). Zipcodes since they don’t nicely overlap city boundaries can cause particular issues in data analysis as well (Grubesic, 2008).

Other Stuff

I have a notebook in the github repo showing how to grab census tracts, as well as how to modify the exact variables you can download.

It does allow you to specify a year as well (in the notebook I show you can do the 2018 SVI for the 16/17/18/19 data at least). Offhand for these small geographies I would only expect small changes over time (see Miles et al., 2016 for an example looking at SES).

One of the things I think has more value added (and hopefully can get some time to do more on this at Gainwell), is to peg these metrics to actual health outcomes – so instead of making an index for SES, look at micro level demographics for health outcomes, and then post-stratify based on census data to get estimates across the US. But that being said, the SVI often does have reasonable correlations to actual geospatial health outcomes, see Learnihan et al. (2022) for one example that medication adherence the SVI is a better predictor than distance for pharmacy for example.

References

Buffalo shootings paper published

My article examining spatial shifts in shootings in Buffalo pre/post Covid, in collaboration with several of my Buffalo colleagues, is now published in the Journal of Experimental Criminology (Drake et al., 2022).

If you do not have access to that journal, you can always just email, or check out the open access pre-print. About the only difference is a supplement we added in response to reviewers, including maps of different grid cell areas, here is a hex grid version of the changes:

The idea behind this paper was to see if given the dramatic increase in shootings in Buffalo after Covid started (Kim & Phillips, 2021), they about doubled (similar to NYC), did spatial hot spots change? The answer is basically no (and I did a similar analysis in NYC as well).

While other papers have pointed out that crime increases disproportionately impact minority communities (Schleimer et al., 2022), which is true, it stands to be very specific what the differences in my work and this are saying. Imagine we have two neighborhoods:

Neighborhood A, Disadvantaged/Minority, Pre 100 crimes, Post 200 crimes
Neighborhood B,    Advantaged/Majority, Pre   1 crimes, Post   2 crimes

The work that I have done has pointed to these increases due to Covid being that relative proportions/rates are about the same (shootings ~doubled in both Buffalo/NYC). And that doubling was spread out pretty much everywhere. It is certainly reasonable to interpret this as an increased burden in minority communities, even if proportional trends are the same everywhere.

This proportional change tends to occur when crime declines as well (e.g. Weisburd & Zastrow, 2022; Wheeler et al., 2016). And this just speaks to the stickiness of hot spots of crime. Even with large macro changes in temporal crime trends, crime hot spots are very durable over time. So I really think it makes the most sense for police departments to have long term strategies to deal with hot spots of crime, and they don’t need to change targeted areas very often.

References

ptools feature engineering vignette update

For another update to my ptools R package in progress, I have added a vignette to go over the spatial feature engineering functions I have organized. These include creating vector spatial features (grid cells, hexagons, or Voronoi polygons), as well as RTM style features on the right hand side (e.g. distance to nearest, kernel density estimates at those polygon centroids, different weighted functions ala egohoods, etc.)

If you do install the package turning vignettes on you can see it:

install_github("apwheele/ptools", build_vignettes = TRUE)
vignette("spat-feateng")

Here is an example of hexgrids over NYC (I have datasets for NYC Shootings, NYC boroughs, NYC Outdoor Cafes, and NYC liquor licenses to illustrate the functions).

The individual functions I think are reasonably documented, but it is somewhat annoying to get an overview of them all. If you go to something like “?Documents/R/win-library/4.1/ptools/html/00Index.html” (or wherever your package installation folder is) you can see all of the functions currently in the package in one place (is there a nice way to pull this up using help()?). But between this vignette and the Readme on the front github page you get a pretty good overview of the current package functionality.

I am still flip flopping whether to bother to submit to CRAN. Installing from github is so easy not sure it is worth the hassle while I continually add in new things to the package. And I foresee tinkering with it for an extended period of time.

Always feel free to contribute, I want to not only add more functions, but should continue to do unit tests and add in more vignettes.

Spatial consistency of shootings and NIJ recid working papers

I have two recent working papers out:

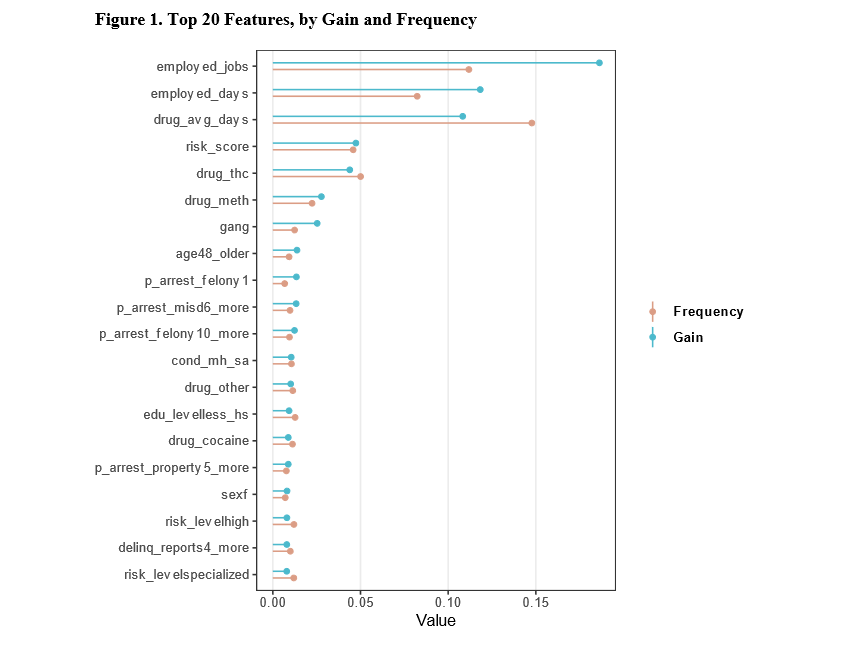
The NIJ forecasting paper is the required submission by NIJ. Gio and I will likely try to turn this into a real paper in the near future. I’d note George Mohler and Michael Porter did the same thing as us, clip the probabilities to under 0.5 to win the fairness competition.

NIJ was interested in “what variables are the most important” – I will need to slate a longer blog post about this in the future, but this generally is not the right way to frame predictive challenges. You do not need real in depth understanding of the underlying system, and many times different effects can be swapped out for one another (e.g. Dawes, 1979).

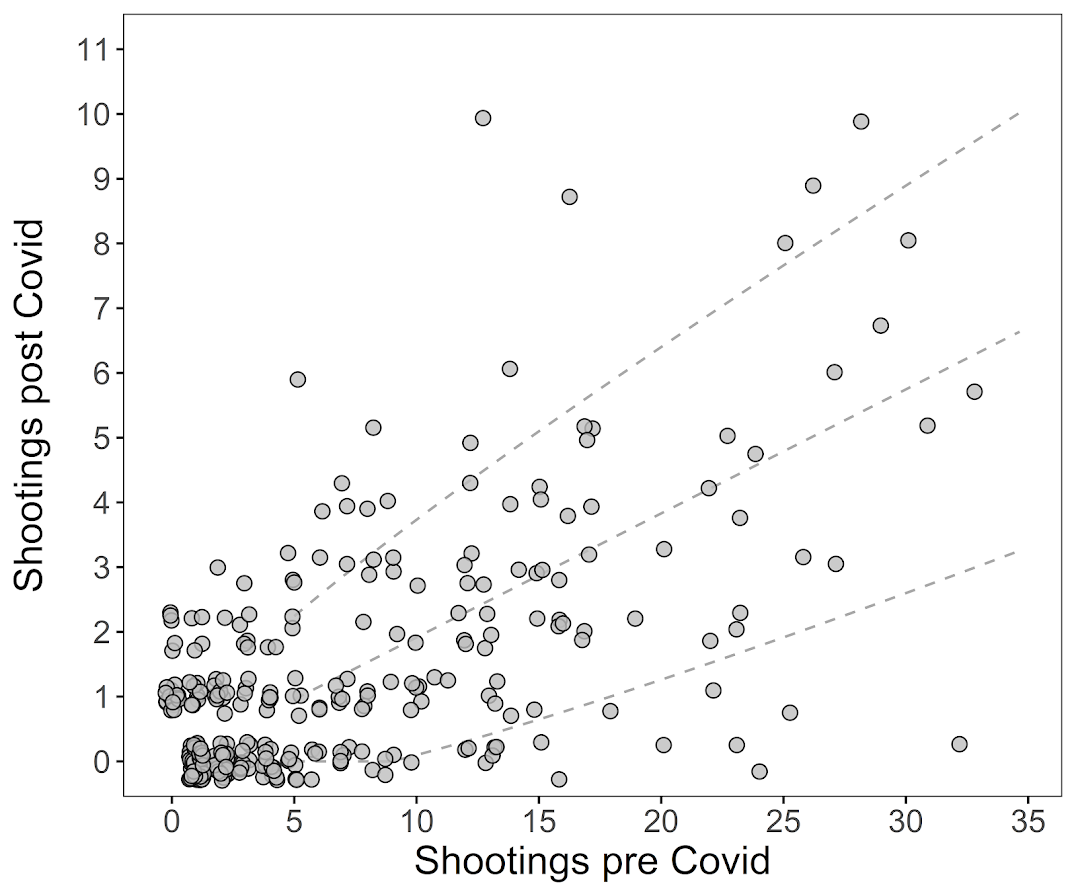
The paper on shootings in Buffalo is consistent with my blog posts on shootings in NYC (precincts, grid cells). Even though shootings have gone up by quite a bit in Buffalo overall, the spatial distribution is very consistent over time. Appears similar to a recent paper by Jeff Brantingham and company as well.

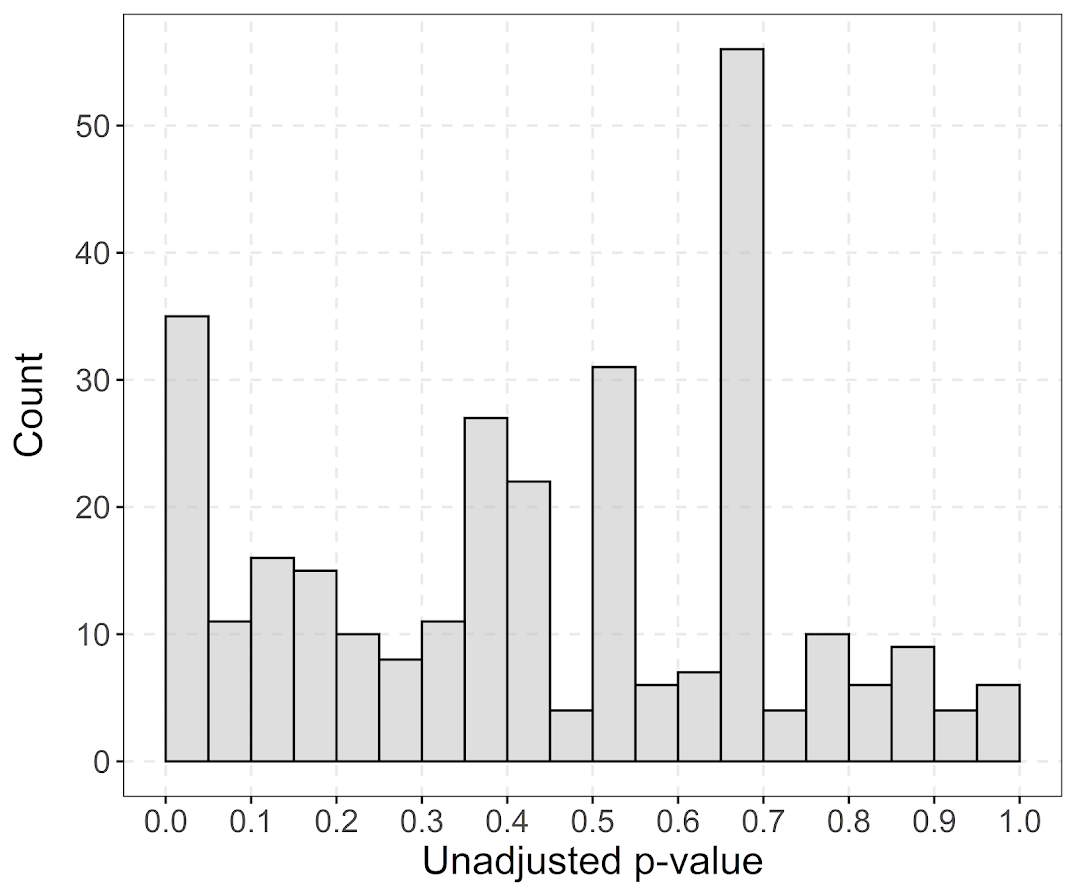
It is a good use case for the differences in SPPT results when adjusting for multiple comparisons, we get a S index of 0.88 without adjustments, (see below distribution of p-values). These are consistent with random data though, so when doing a false discovery rate correction we have 0 areas below 0.05.

If you look at the maps there are some fuzzy evidence of shifts, but it is quite weak overall. Also one thing I mention here is that even though we have hot spots of shootings, even the hottest grid cells only have 1 shooting a month. Not clear to me if that is sufficient density (if only considering shootings) to really justify a hot spots approach.

References

  • Brantingham, P. J., Carter, J., MacDonald, J., Melde, C., & Mohler, G. (2021). Is the recent surge in violence in American cities due to contagion?. Journal of Criminal Justice, 76, 101848.
  • Circo, G., & Wheeler, A. (2021). National Institute of Justice Recidivism Forecasting Challenge Team “MCHawks” Performance Analysis. CrimRxiv. https://doi.org/10.21428/cb6ab371.9aa2c75a
  • Dawes, R. M. (1979). The robust beauty of improper linear models in decision making. American Psychologist, 34(7), 571.
  • Drake, G., Wheeler, A., Kim, D.-Y., Phillips, S. W., & Mendolera, K. (2021). The Impact of COVID-19 on the Spatial Distribution of Shooting Violence in Buffalo, NY. CrimRxiv. https://doi.org/10.21428/cb6ab371.e187aede
  • Mohler, G., & Porter, M. D. (2021). A note on the multiplicative fairness score in the NIJ recidivism forecasting challenge. Crime Science, 10(1), 1-5.